 HREN


Nanbeige4.3-33B publishes JobBench scores across 35 occupationsNanbeige4.3-33B, 35개 직업별 성능표 공개
The open model's model card compares JobBench scores by occupation. In the developer's own evaluation, technical writing and online selling scored high, while customer service and administrative support scored lower than a comparison model.공개 모델의 JobBench 점수를 직업별로 비교했습니다. 개발사 평가에서는 기술 문서 작성·온라인 판매와 고객 상담·사무 보조의 결과가 갈렸습니다.
- Source published원문 게시일
- Checked확인일
- Posted게시일
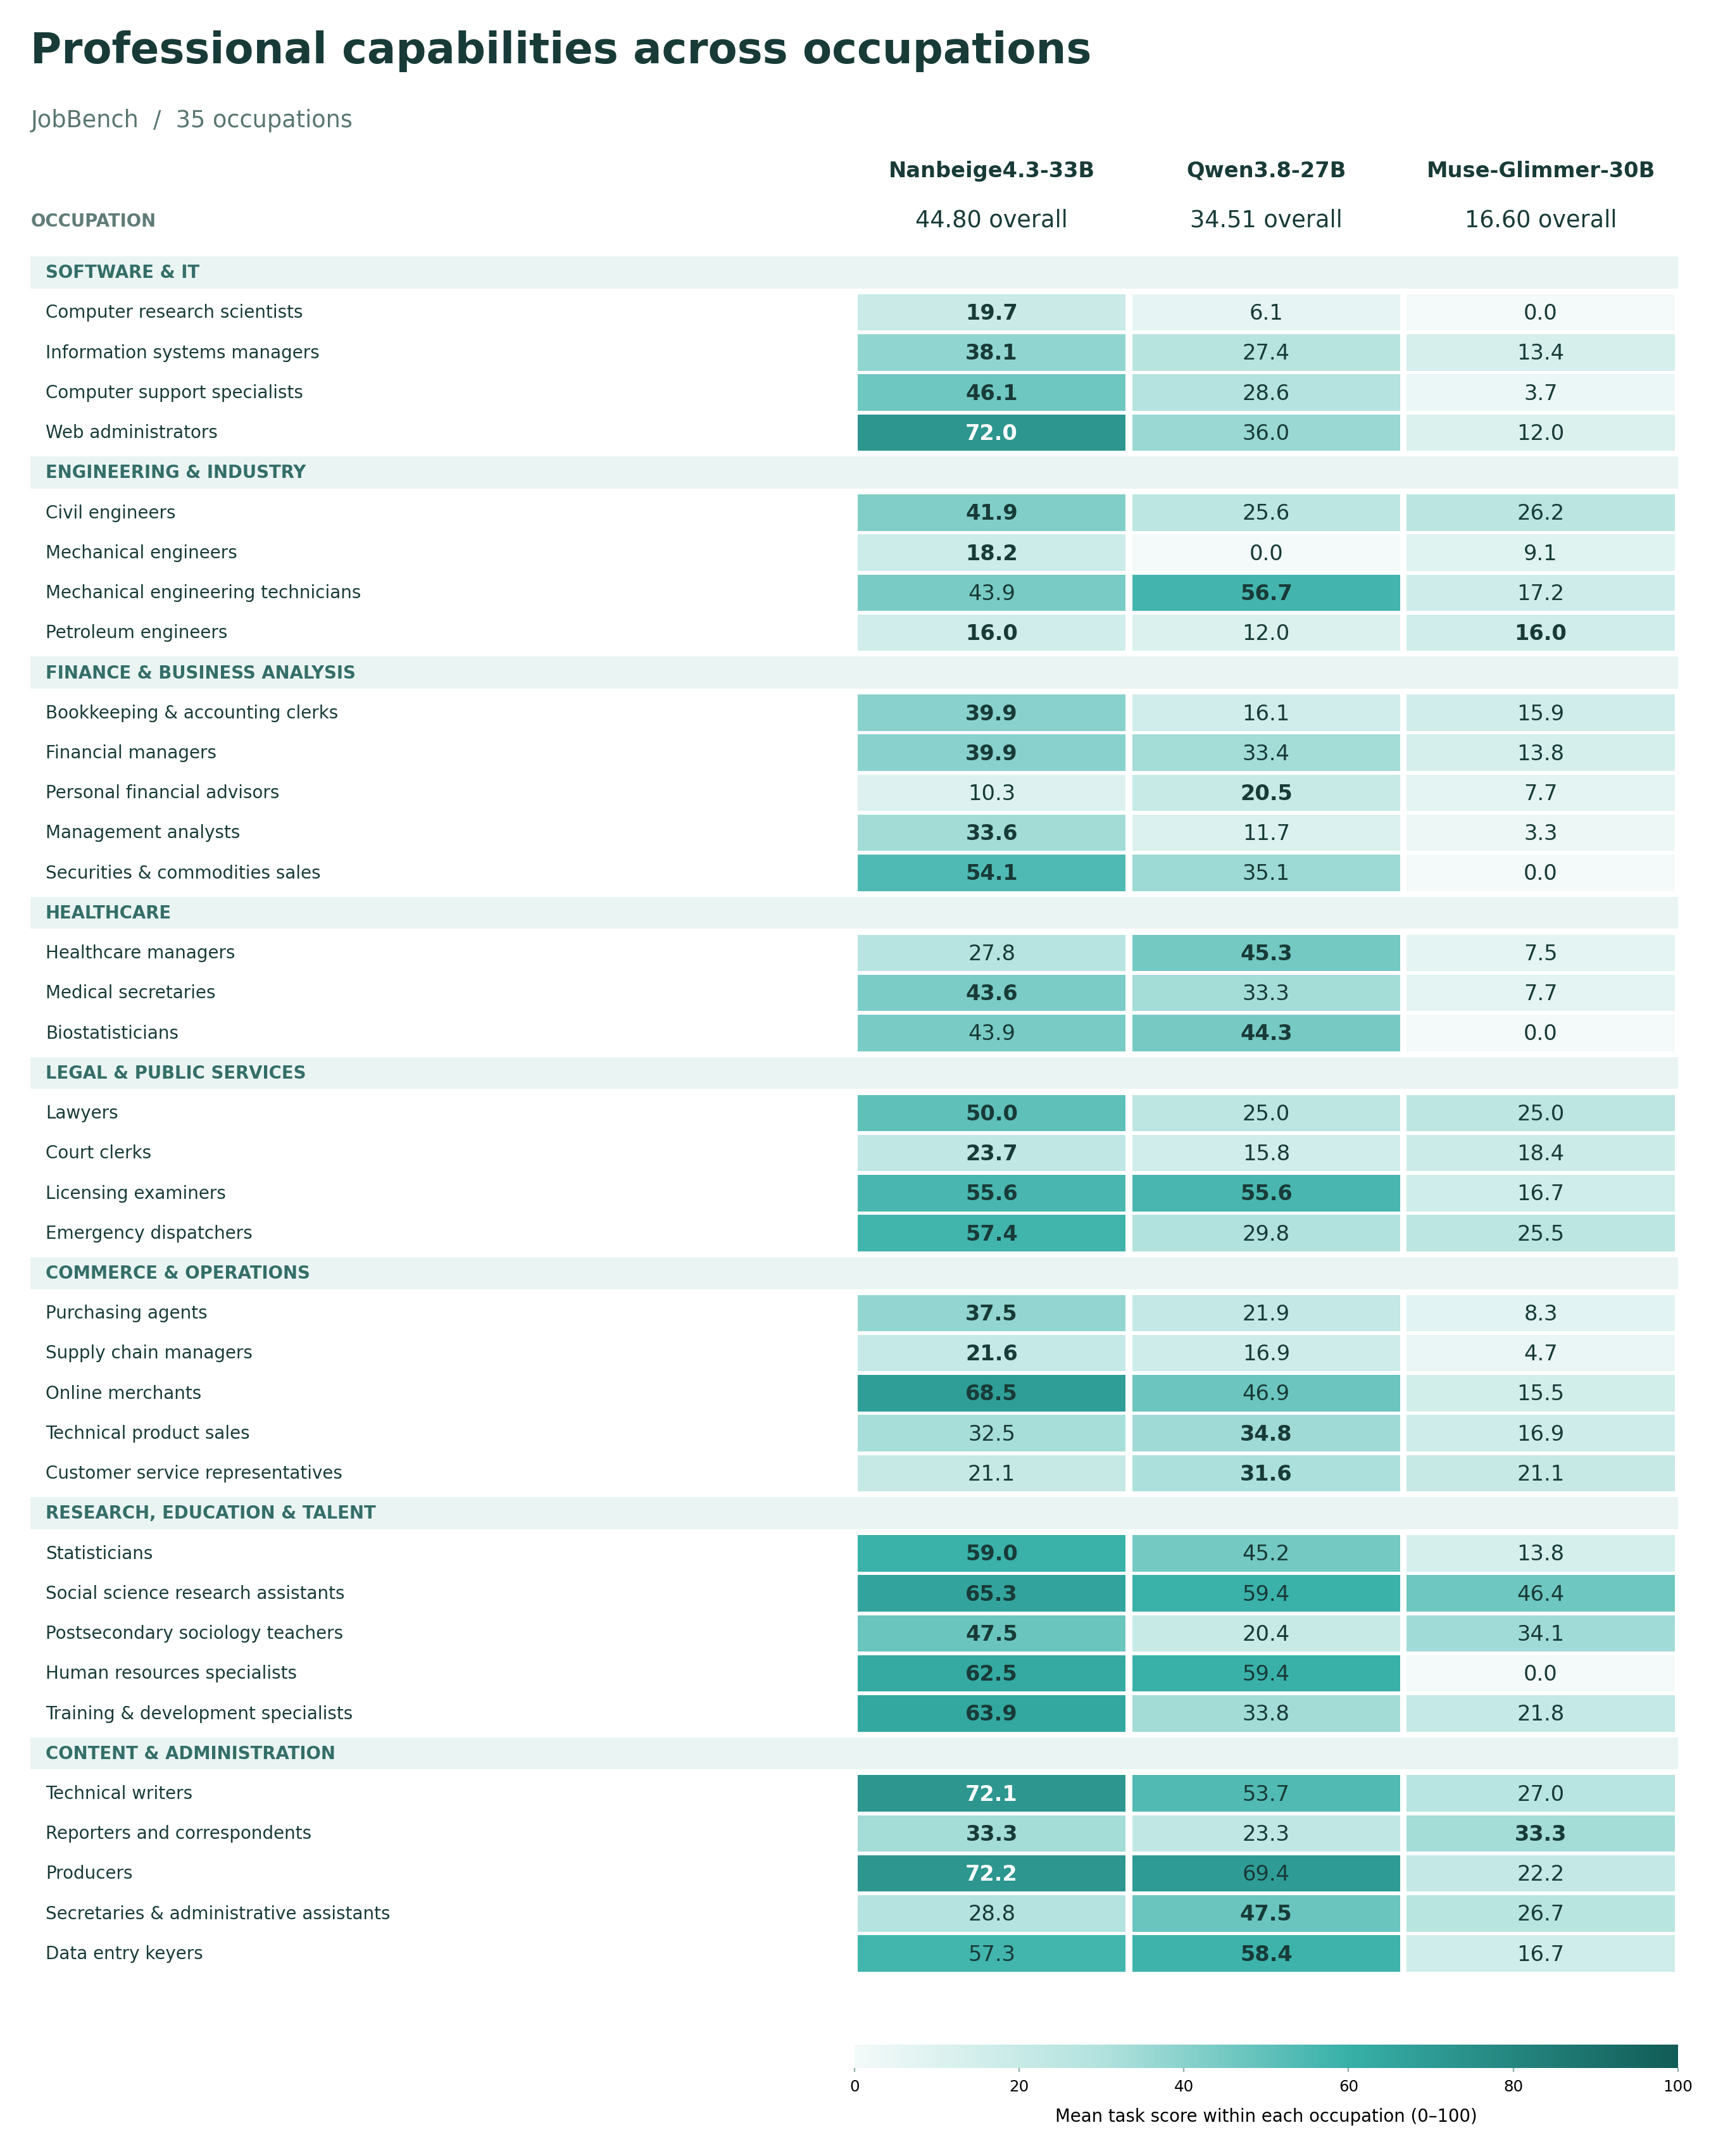
Nanbeige has released the language model Nanbeige4.3-33B on Hugging Face. The model card introduces it as the flagship teacher model for the Nanbeige4.3 series. Nanbeige said it delivers state-of-the-art agentic performance among open models in the roughly 30B-parameter class and excels at complex coding and professional cowork tasks.Nanbeige가 언어 모델 Nanbeige4.3-33B를 Hugging Face에 공개했습니다. 모델 카드는 이 모델을 Nanbeige4.3 시리즈의 대표 교사 모델(flagship teacher model)로 소개합니다. Nanbeige는 약 30B 파라미터급 공개 모델 가운데 최고 수준의 에이전트 성능을 낸다고 밝혔고, 복잡한 코딩과 전문 협업(professional cowork) 작업에 강하다고 설명했습니다.
The model can be run with Transformers, SGLang or vLLM. In the chat template, enable_thinking controls whether the model generates reasoning for the response and is on by default. preserve_thinking controls whether reasoning from earlier turns is kept; the model card recommends False for general chat and question answering and True for multi-turn tool use, office tasks and code-agent workflows. It recommends the xml tool-call format and also supports json. The maximum context length is 524,288 tokens (512K).모델은 Transformers, SGLang, vLLM으로 실행할 수 있습니다. 채팅 템플릿의 enable_thinking은 응답에서 추론을 생성할지 정하며 기본으로 켜져 있습니다. preserve_thinking은 이전 턴의 추론을 대화에 남길지 정하는데, 모델 카드는 일반 대화와 질의응답에는 False, 여러 턴에 걸친 도구 사용·사무 작업·코드 에이전트 작업에는 True를 권장합니다. 도구 호출은 xml 형식을 권장하고 json 형식도 지원합니다. 최대 컨텍스트 길이는 524,288토큰(512K)입니다.
The model card's benchmark table compares Nanbeige4.3-33B with models of around 30B parameters: Qwen3.8-27B, Muse-Glimmer-30B and Gemma4-31B. Nanbeige said all models were evaluated at their highest thinking effort, with the same inference hyperparameters and harness. A footnote in the model card says Nanbeige4.3-33B was evaluated in this table with preserve_thinking=true in the chat template. On JobBench, run in a Claude Code harness with a search tool, the overall scores are 44.8 for Nanbeige4.3-33B, 34.5 for Qwen3.8-27B, 16.6 for Muse-Glimmer-30B and 9.0 for Gemma4-31B.모델 카드의 성능표는 Nanbeige4.3-33B를 30B 안팎의 모델인 Qwen3.8-27B, Muse-Glimmer-30B, Gemma4-31B와 비교합니다. Nanbeige는 모든 모델을 가장 높은 추론 강도(highest thinking effort)로, 같은 추론 설정과 평가 도구로 평가했다고 밝혔습니다. 모델 카드 각주에 따르면 이 표의 Nanbeige4.3-33B는 채팅 템플릿에서 preserve_thinking=true로 평가됐습니다. 검색 도구를 붙인 Claude Code 환경에서 잰 JobBench 전체 점수는 Nanbeige4.3-33B 44.8, Qwen3.8-27B 34.5, Muse-Glimmer-30B 16.6, Gemma4-31B 9.0입니다.
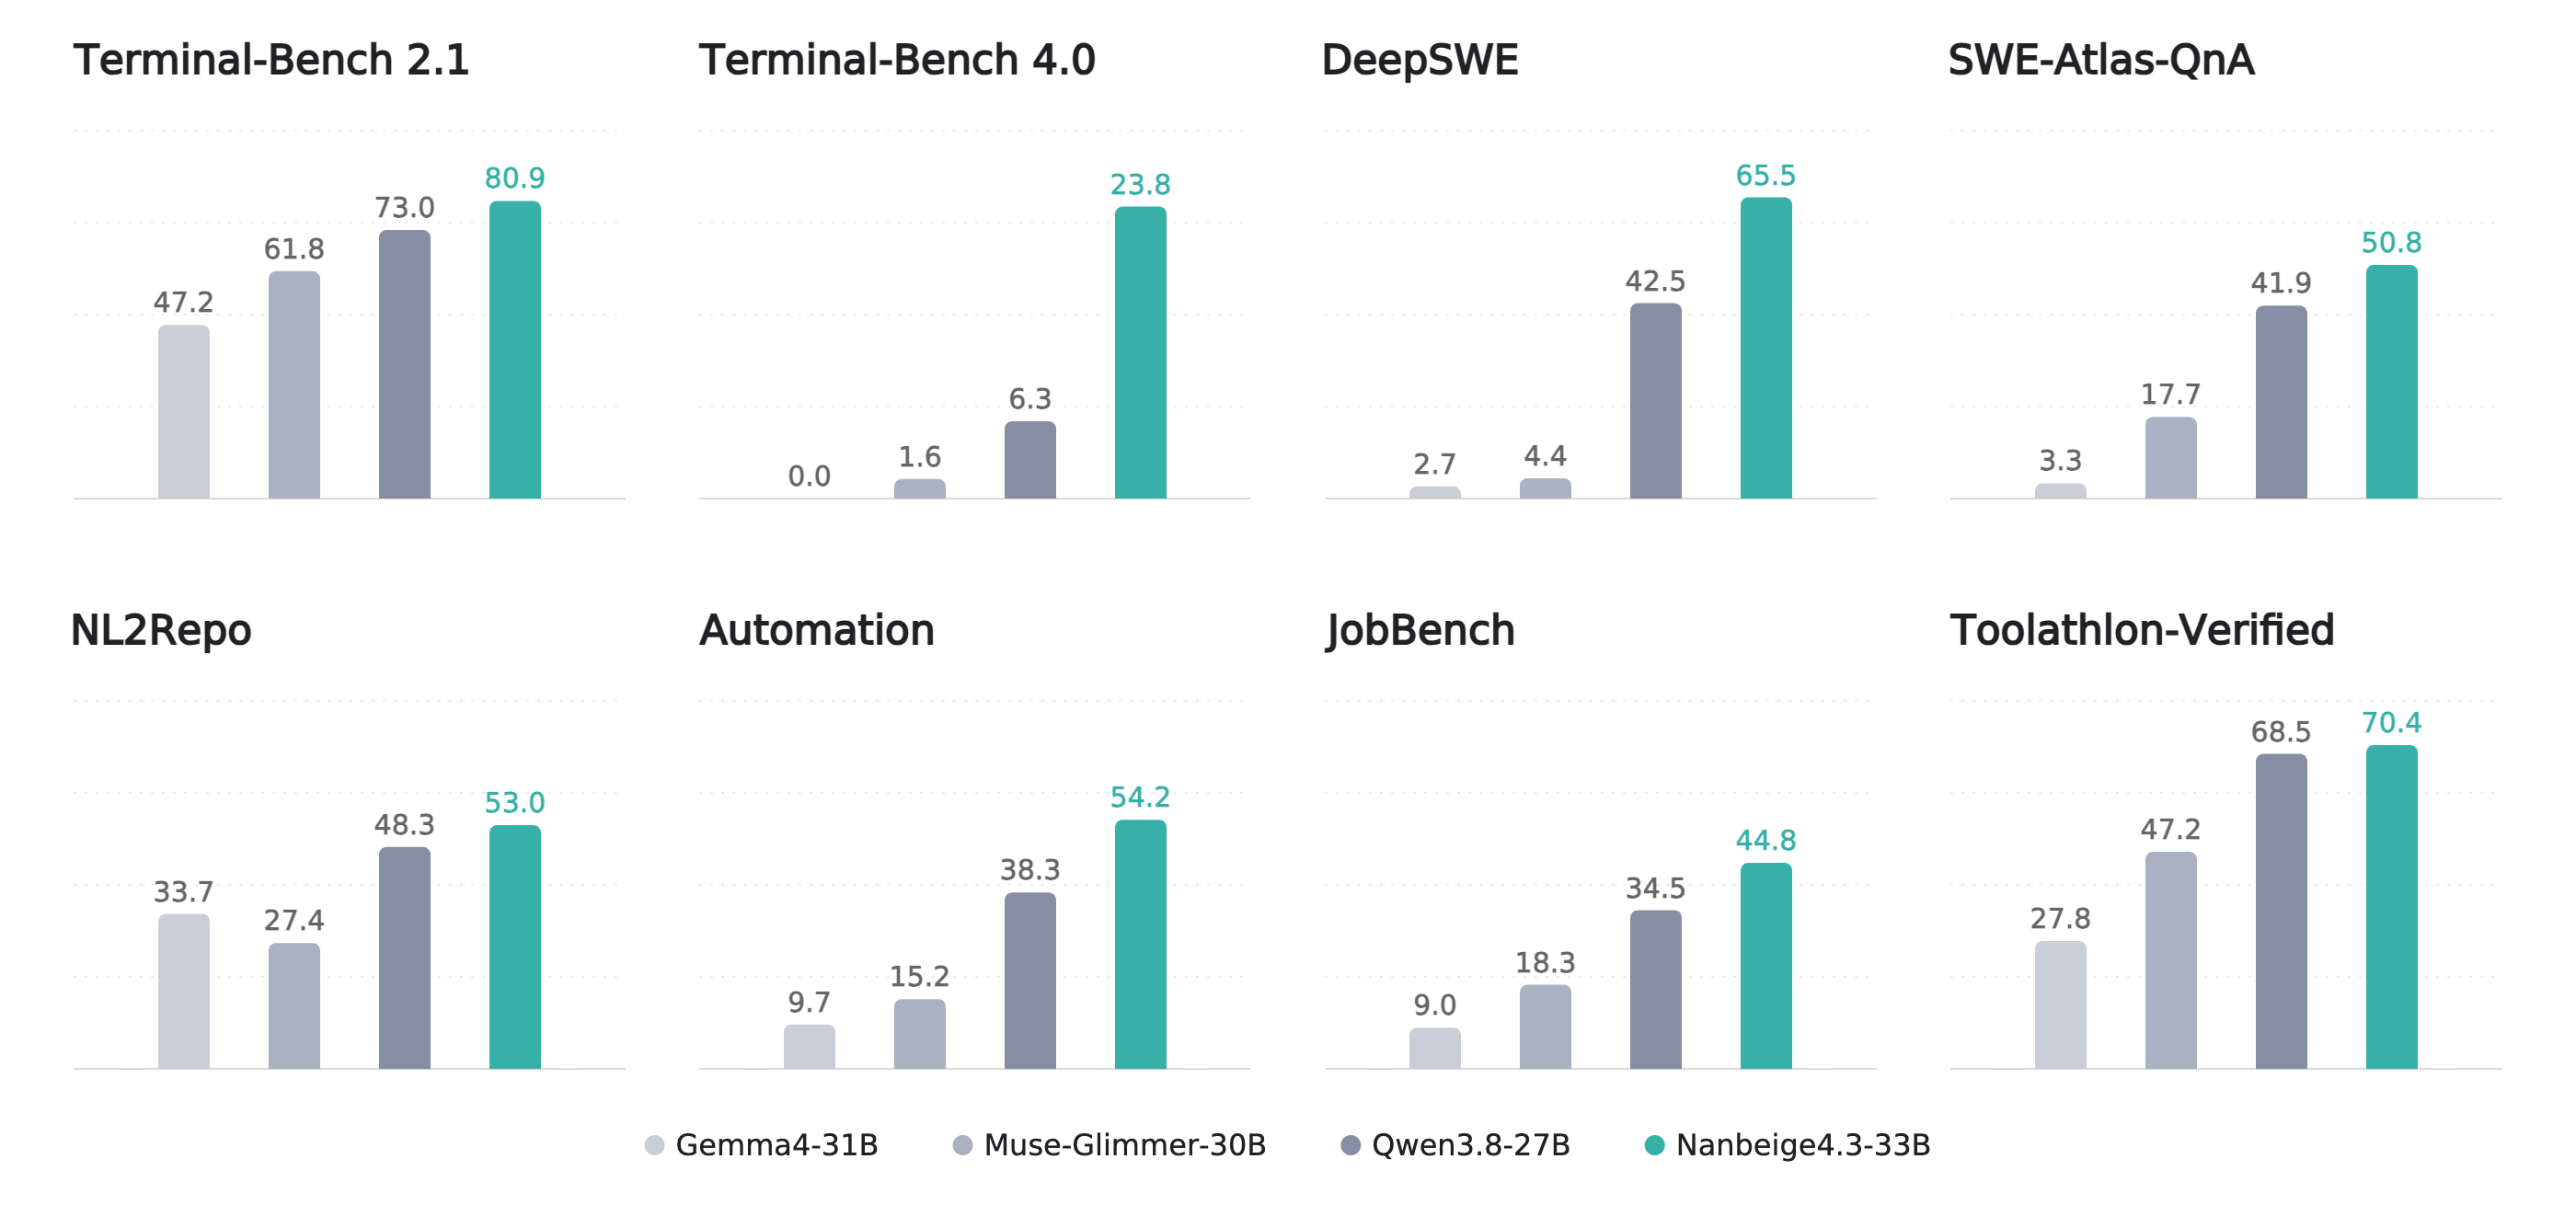
The JobBench results are also published as a table of 35 occupations. Each score is the mean task score within that occupation (0–100). Technical writers scored 72.1, against 53.7 for Qwen3.8-27B, and online merchants 68.5, against 46.9. In contrast, customer service representatives scored 21.1, below Qwen3.8-27B's 31.6, and secretaries & administrative assistants 28.8, below 47.5.JobBench 결과는 35개 직업별 표로도 공개됐습니다. 표의 점수는 직업마다 과제 점수를 평균한 값(0~100)입니다. 기술 문서 작성자(Technical writers)는 72.1로 Qwen3.8-27B의 53.7보다, 온라인 판매자(Online merchants)는 68.5로 46.9보다 높았습니다. 반대로 고객 서비스 상담원(Customer service representatives)은 21.1로 Qwen3.8-27B의 31.6보다, 비서·사무 보조원(Secretaries & administrative assistants)은 28.8로 47.5보다 낮았습니다.
The model is in the Nanbeige/Nanbeige4.3-33B repository on Hugging Face under the Apache 2.0 license. Its base model is listed as Nanbeige4.3-33B-Base, and the model card's language field lists English (en) and Chinese (zh). A release date, pricing and a hosted API are not stated in the model card.모델은 Hugging Face의 Nanbeige/Nanbeige4.3-33B 저장소에 있고, 라이선스는 Apache 2.0입니다. 기반 모델로는 Nanbeige4.3-33B-Base가 적혀 있고, 모델 카드의 언어 칸에는 영어(en)와 중국어(zh)가 있습니다. 공개 날짜, 사용료, 호스팅 API 안내는 모델 카드에 나와 있지 않습니다.
All figures in the tables are Nanbeige's own published evaluations. Nanbeige said the model leads on most of the benchmarks and, on JobBench, outperforms the baseline in most of the 35 occupations evaluated. In the same table, it scored 60.3 on SWE-Bench Pro against Qwen3.8-27B's 61.7, 84.8 on GDPval against 86.4, and 89.5 on GPQA Diamond against Gemma4-31B's 91.3. Safety evaluations and known limitations are not stated in the model card.표의 숫자는 모두 Nanbeige가 직접 평가해 공개한 결과입니다. Nanbeige는 대부분의 벤치마크에서 앞선다고 밝혔고, JobBench에서도 평가한 35개 직업 대부분에서 비교 모델보다 높다고 설명했습니다. 같은 표에서 SWE-Bench Pro는 60.3으로 Qwen3.8-27B의 61.7보다, GDPval은 84.8로 86.4보다 낮았고, GPQA Diamond는 89.5로 Gemma4-31B의 91.3보다 낮았습니다. 안전 평가나 알려진 한계를 다룬 내용은 모델 카드에 나와 있지 않습니다.
Nanbeige described Nanbeige4.3 as a foundational step toward pushing the boundaries of lightweight agents: build a high-capacity teacher agent first, then distill its agentic capabilities into smaller models. The company said this 33B model lays the foundation for its upcoming small-model distillation pipeline, for example for Nanbeige4.3-3B. The model card does not state when the 3B model will be released.Nanbeige는 Nanbeige4.3을 가벼운 에이전트의 한계를 넓히는 기초 단계로 소개하며, 먼저 큰 교사 에이전트를 만든 뒤 그 에이전트 능력을 더 작은 모델로 증류(distillation)하는 전략이라고 밝혔습니다. 회사는 이번 33B 모델이 Nanbeige4.3-3B 같은 작은 모델을 위해 앞으로 나올 증류 파이프라인의 바탕이 된다고 설명했습니다. 3B 모델의 공개 시기는 모델 카드에 나와 있지 않습니다.
Sources & references원문과 참고 자료
Keep reading더 읽기
All articles전체 글TencentTencent
Tencent releases Hy4 flash as open weights, with FP8 and base versions, under the Tencent Hy LicenseTencent, Hy4 flash 가중치 공개 — FP8 · base 모델 포함, Tencent Hy License
Checked확인일
Chart: Tencent Hy4 flash model card. Tencent internal testing.그림: Tencent Hy4 flash 모델 카드. Tencent 내부 시험 결과입니다.
ElevenLabsElevenLabs
ElevenLabs releases Scribe v3 Live Medical, real-time medical transcription for voice agents in ElevenAgentsElevenLabs, ElevenAgents 음성 에이전트용 실시간 의료 전사 Scribe v3 Live Medical 공개
Checked확인일
Image: ElevenLabs blog.그림: ElevenLabs 블로그.
GoogleGoogle
Google launches a Robotics plugin for Google Antigravity that sets up, simulates and controls robot arms with Gemini 4 HydrogenGoogle, Gemini 4 Hydrogen으로 로봇 팔을 준비·시뮬레이션·제어하는 Google Antigravity용 Robotics 플러그인 공개
Checked확인일
Video still: Google Developers Blog.영상 장면: Google Developers 블로그.


