 HREN


NVIDIA releases Nemotron 3.5 Transcribe, an open-weight speech model for 40 languages and recordings up to one hourNVIDIA Nemotron 3.5 Transcribe 공개, 40개 언어·최대 1시간 녹음을 받아 적는 오픈 웨이트 모델
An offline model that takes a recording and an instruction for transcription, translation, speaker attribution and audio question answering. The weights are on Hugging Face under the OpenMDW-1.1 license.녹음과 지시문을 받아 받아쓰기, 번역, 화자 구분, 오디오 질의응답을 하는 오프라인 모델입니다. Hugging Face에 가중치가 올라왔고 OpenMDW-1.1 사용권을 따릅니다.
- Source published원문 게시일
- Checked확인일
- Posted게시일
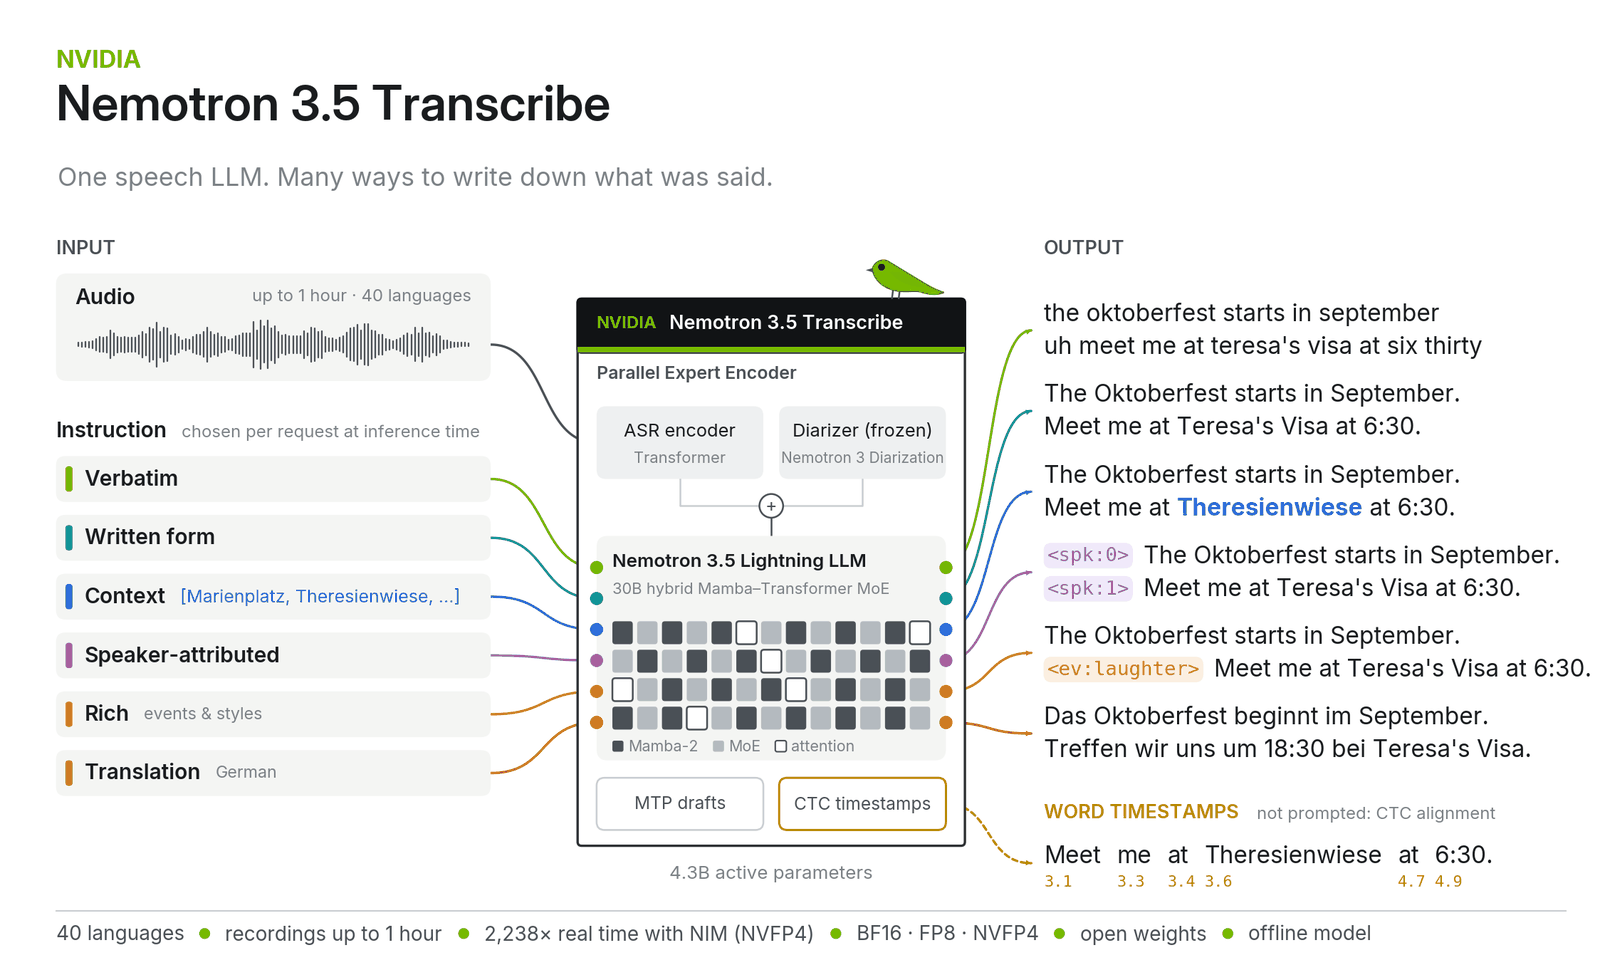
NVIDIA released Nemotron 3.5 Transcribe, a speech and audio model, on Hugging Face. The model card describes it as an open-weight, offline speech and audio model for transcription in 40 languages, with support for recordings up to one hour and a 65,536-token context. It is a Speech-Augmented Language Model (SALM) that takes a recording, a text instruction and optional context and answers in text.NVIDIA가 음성·오디오 모델 Nemotron 3.5 Transcribe를 Hugging Face에 공개했습니다. 모델 카드는 이 모델을 40개 언어 받아쓰기를 위한 오픈 웨이트 오프라인 음성·오디오 모델이라고 소개하며, 최대 1시간 녹음과 65,536토큰 컨텍스트를 지원한다고 밝혔습니다. 녹음과 텍스트 지시, 선택적 문맥을 받아 텍스트로 답하는 음성 증강 언어 모델(SALM)입니다.
NVIDIA lists multilingual transcription, speech translation, contextual transcription, speaker-attributed transcription, rich transcription that marks events such as laughter, timestamp prediction, language identification and audio question answering as its tasks. The transcription style is chosen per request through the instruction: word-for-word with fillers, readable text, names and terms given as context, or speaker tags; with timestamp capture enabled in vLLM, each word comes with start and end times and a speaker tag. Speaker tags must be requested when speaker attribution is needed; a transcript without speaker tags is aligned as a single speaker. The model can run behind the OpenAI-compatible API of a vLLM or SGLang-Omni server or with Hugging Face Transformers, and can be fine-tuned with NeMo Speech, the company explains. Word timestamps, speaker-attributed output, translation and speculative decoding are not part of the SGLang-Omni integration.NVIDIA는 할 일로 다국어 받아쓰기, 음성 번역, 문맥을 넣은 받아쓰기, 화자를 구분한 받아쓰기, 웃음 같은 사건을 표시하는 받아쓰기, 타임스탬프 예측, 언어 판별, 오디오 질의응답을 들었습니다. 받아쓰기 방식은 요청마다 지시문으로 고릅니다. 군말까지 그대로 적을지, 읽기 쉬운 글로 적을지, 이름과 용어를 문맥으로 줄지, 화자 표시를 붙일지를 지시문으로 정하고, vLLM에서 단어별 타임스탬프를 켜면 단어마다 시작·끝 시각과 화자 표시가 함께 나옵니다. 화자 표시가 필요하면 화자 태그를 요청해야 하고, 화자 태그 없는 받아쓰기는 한 화자로 맞춰집니다. vLLM이나 SGLang-Omni 서버의 OpenAI 호환 API, Hugging Face Transformers로 실행할 수 있고 NeMo Speech로 미세 조정할 수 있다고 설명했습니다. SGLang-Omni 연동에는 단어별 타임스탬프, 화자 표시 출력, 번역, 추측 디코딩이 들어 있지 않습니다.
According to the model card, it has 34B parameters in total, including the audio encoder, of which about 4.3B are active, in a hybrid mixture-of-experts (MoE) architecture. In the model card's results, its mean word error rate (WER) on nine English sets of the Open ASR Leaderboard was 4.71%, the lowest among open-weight models, ahead of Qwen3-ASR-1.7B at 4.94%. Its mean cpWER for multi-speaker transcription was 15.80%, which the company says is the best published result. The model card describes these as results captured on October 12, 2026. NVIDIA also says that with the optimized vLLM implementation in the Nemotron Transcribe NIM, one RTX PRO 6000 Blackwell Server Edition GPU transcribes up to 2,238 seconds of audio per second (NVFP4 with DFlash2 speculative decoding).모델 카드에 따르면 오디오 인코더를 포함한 전체 매개변수는 340억 개이고, 그 가운데 약 43억 개가 활성화되는, Mamba-2와 Transformer를 함께 쓰는 전문가 혼합(MoE) 구조입니다. 모델 카드의 결과로는 Open ASR Leaderboard 영어 9개 세트 평균 단어 오류율(WER)이 4.71%로 공개 가중치 모델 가운데 가장 낮았고, 다음은 Qwen3-ASR-1.7B의 4.94%였습니다. 여러 화자 받아쓰기의 평균 cpWER는 15.80%로 발표된 결과 가운데 가장 낮았다고 밝혔습니다. 모델 카드는 이 결과를 10월 12일 기준 결과(Results captured on October 12, 2026)라고 적었습니다. NVIDIA는 Nemotron Transcribe NIM의 최적화된 vLLM 구현으로 RTX PRO 6000 Blackwell Server Edition GPU 한 장이 초당 최대 2,238초 분량의 오디오를 받아쓴다고(NVFP4 · DFlash2 추측 디코딩 기준) 밝혔습니다.
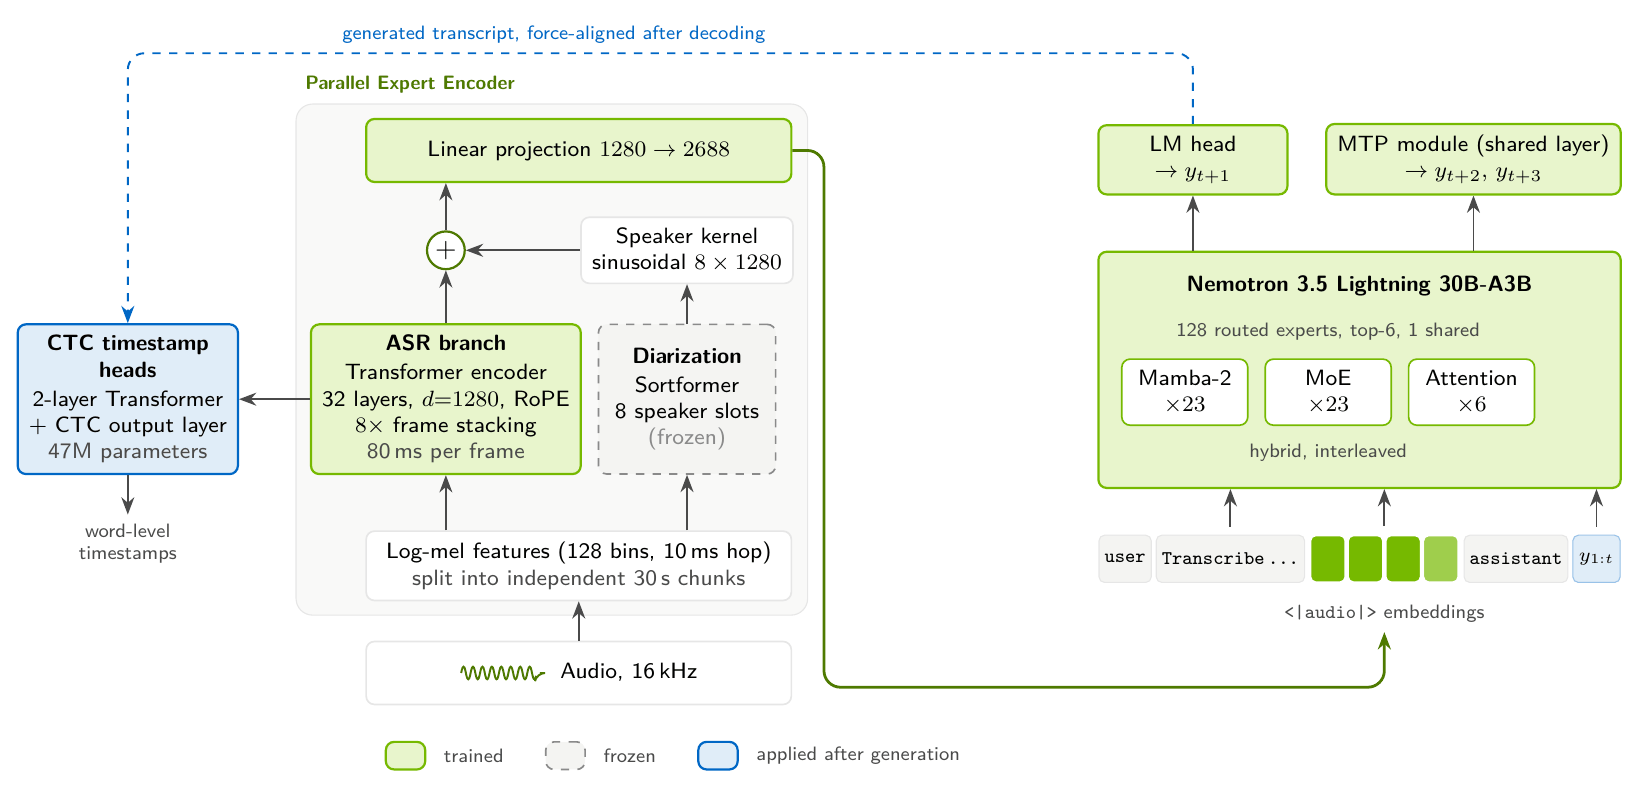
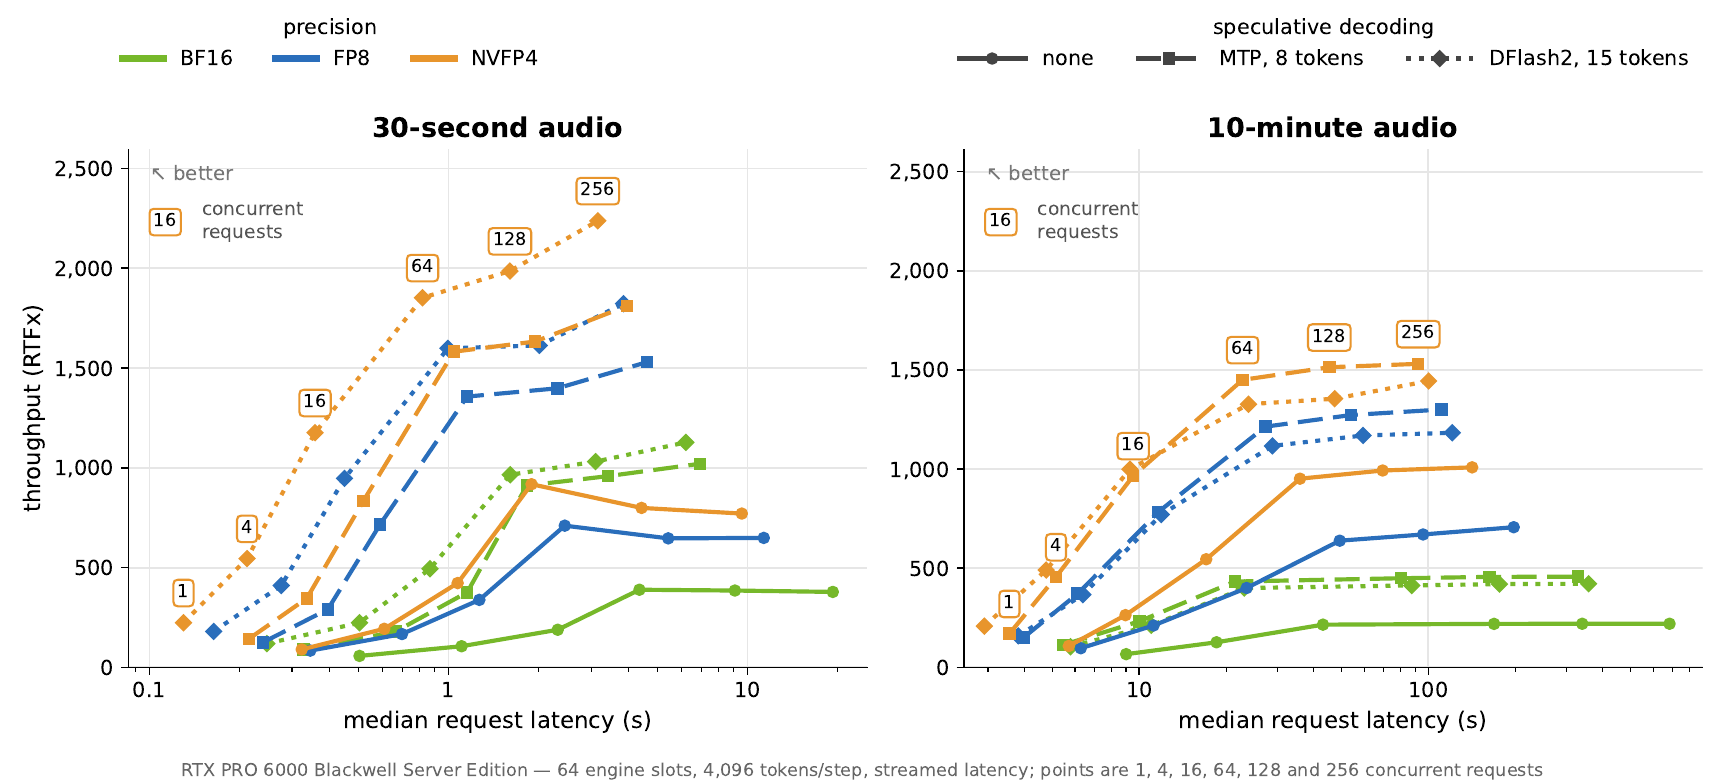
The weights are on Hugging Face in BF16, FP8 and NVFP4 versions under the OpenMDW-1.1 license, and the model card says the model is ready for commercial or non-commercial use. The deployment geography is global, and the release date is October 28 on Hugging Face, GitHub, NGC and build.nvidia.com. One H100 80 GB GPU is given as the deployment example. Pricing is not stated in the model card.가중치는 Hugging Face에 BF16, FP8, NVFP4 세 가지 정밀도로 올라와 있고, 사용권은 OpenMDW-1.1이며, 모델 카드는 상업·비상업 용도로 쓸 수 있다고 적었습니다. 배포 지역은 전 세계이고, 공개일은 Hugging Face, GitHub, NGC, build.nvidia.com 모두 10월 28일입니다. 배치 예로는 H100 80GB 한 장을 들었습니다. 요금은 모델 카드에 나와 있지 않습니다.
NVIDIA says this is an offline model and that its internal audio chunking does not make it a real-time streaming transcription service. It was trained with recordings up to one hour and a 65,536-token context, and generalization beyond these limits is not guaranteed. Language and task support vary by language, and speaker labels distinguish speakers within a recording without establishing real-world identity, the company explains. The serving optimizations behind the throughput figure are not yet part of the open-source release, and the vLLM integration shipped in NeMo Speech on release day is intended for model development and is expected to be roughly two times slower, the company says.NVIDIA는 이 모델이 오프라인 모델이며, 내부 오디오 분할이 있어도 실시간 스트리밍 받아쓰기 서비스는 아니라고 밝혔습니다. 학습은 최대 1시간 녹음과 65,536토큰 컨텍스트로 했고, 그 범위를 넘어선 일반화는 보장하지 않습니다. 지원하는 언어와 작업은 언어마다 다르고, 화자 표시는 한 녹음 안의 화자를 구분할 뿐 실제 신원을 확인하지 않는다고 설명했습니다. 앞의 처리 속도를 낸 서빙 최적화는 아직 오픈소스 배포에 들어 있지 않고, 공개일에 NeMo Speech로 나온 vLLM 연동은 모델 개발용이라 약 2배 느릴 것이라고 회사는 밝혔습니다.
Sources & references원문과 참고 자료
- NVIDIA model card on Hugging FaceHugging Face의 NVIDIA 공식 모델 카드
- NVIDIA AI announcement on XNVIDIA AI 공식 X 발표
- NVIDIA AI post on X about availabilityNVIDIA AI 공식 X 글(공개 자리)
- Speech-Augmented Language Model (SALM) paper linked from the model card모델 카드가 건 음성 증강 언어 모델(SALM) 논문
- NVIDIA live demo on Hugging FaceHugging Face의 NVIDIA 시험 페이지
- NeMo Speech repository on GitHubGitHub의 NeMo Speech 저장소
- Granary-v2 dataset on Hugging FaceHugging Face의 Granary-v2 데이터셋
- SGLang-Omni repository on GitHubGitHub의 SGLang-Omni 저장소
Keep reading더 읽기
All articles전체 글TencentTencent
Tencent releases Hy4 flash as open weights, with FP8 and base versions, under the Tencent Hy LicenseTencent, Hy4 flash 가중치 공개 — FP8 · base 모델 포함, Tencent Hy License
Checked확인일
Chart: Tencent Hy4 flash model card. Tencent internal testing.그림: Tencent Hy4 flash 모델 카드. Tencent 내부 시험 결과입니다.
ElevenLabsElevenLabs
ElevenLabs releases Scribe v3 Live Medical, real-time medical transcription for voice agents in ElevenAgentsElevenLabs, ElevenAgents 음성 에이전트용 실시간 의료 전사 Scribe v3 Live Medical 공개
Checked확인일
Image: ElevenLabs blog.그림: ElevenLabs 블로그.
GoogleGoogle
Google launches a Robotics plugin for Google Antigravity that sets up, simulates and controls robot arms with Gemini 4 HydrogenGoogle, Gemini 4 Hydrogen으로 로봇 팔을 준비·시뮬레이션·제어하는 Google Antigravity용 Robotics 플러그인 공개
Checked확인일
Video still: Google Developers Blog.영상 장면: Google Developers 블로그.


