 HREN


Meituan releases the LongCat-2.5 weights on Hugging Face under the MIT licenseMeituan, LongCat-2.5 가중치를 Hugging Face에 MIT 라이선스로 공개
Meituan has released the weights for LongCat-2.5 on Hugging Face under the MIT license. Meituan puts the model at 1.6 trillion total parameters with about 48 billion activated per token, and the weight files on Hugging Face add up to about 3.56 TB.Meituan이 LongCat-2.5의 가중치를 Hugging Face에 MIT 라이선스로 공개했습니다. Meituan이 밝힌 규모는 전체 매개변수 1.6조 개에 토큰마다 약 480억 개 활성화이고, Hugging Face에 올라온 가중치 파일은 합쳐 약 3.56TB입니다.
- Source published원문 게시일
- Checked확인일
Meituan has released the weights for LongCat-2.5 on Hugging Face. The license is MIT. The model card describes LongCat-2.5 as a native multimodal MoE model for long-horizon agentic tasks. By Meituan's account it has 1.6 trillion total parameters, with about 48 billion activated per token. Building on LongCat-2.0, it combines visual understanding with agentic coding, and the card names complex codebase development, full-project builds, creative design and 3D tasks as its targets.Meituan이 LongCat-2.5의 가중치를 Hugging Face에 공개했습니다. 라이선스는 MIT입니다. 모델 카드는 LongCat-2.5를 오래 이어지는 에이전트 작업을 위한 네이티브 멀티모달 MoE 모델이라고 소개합니다. Meituan이 밝힌 규모는 전체 매개변수 1.6조 개이고, 토큰 하나를 처리할 때 약 480억 개가 활성화됩니다. LongCat-2.0을 바탕으로 시각 이해와 에이전트 코딩을 한 모델에 합쳤고, 복잡한 코드베이스 개발과 프로젝트 전체 빌드, 디자인, 3D 작업을 대상으로 든다고 카드는 적었습니다.
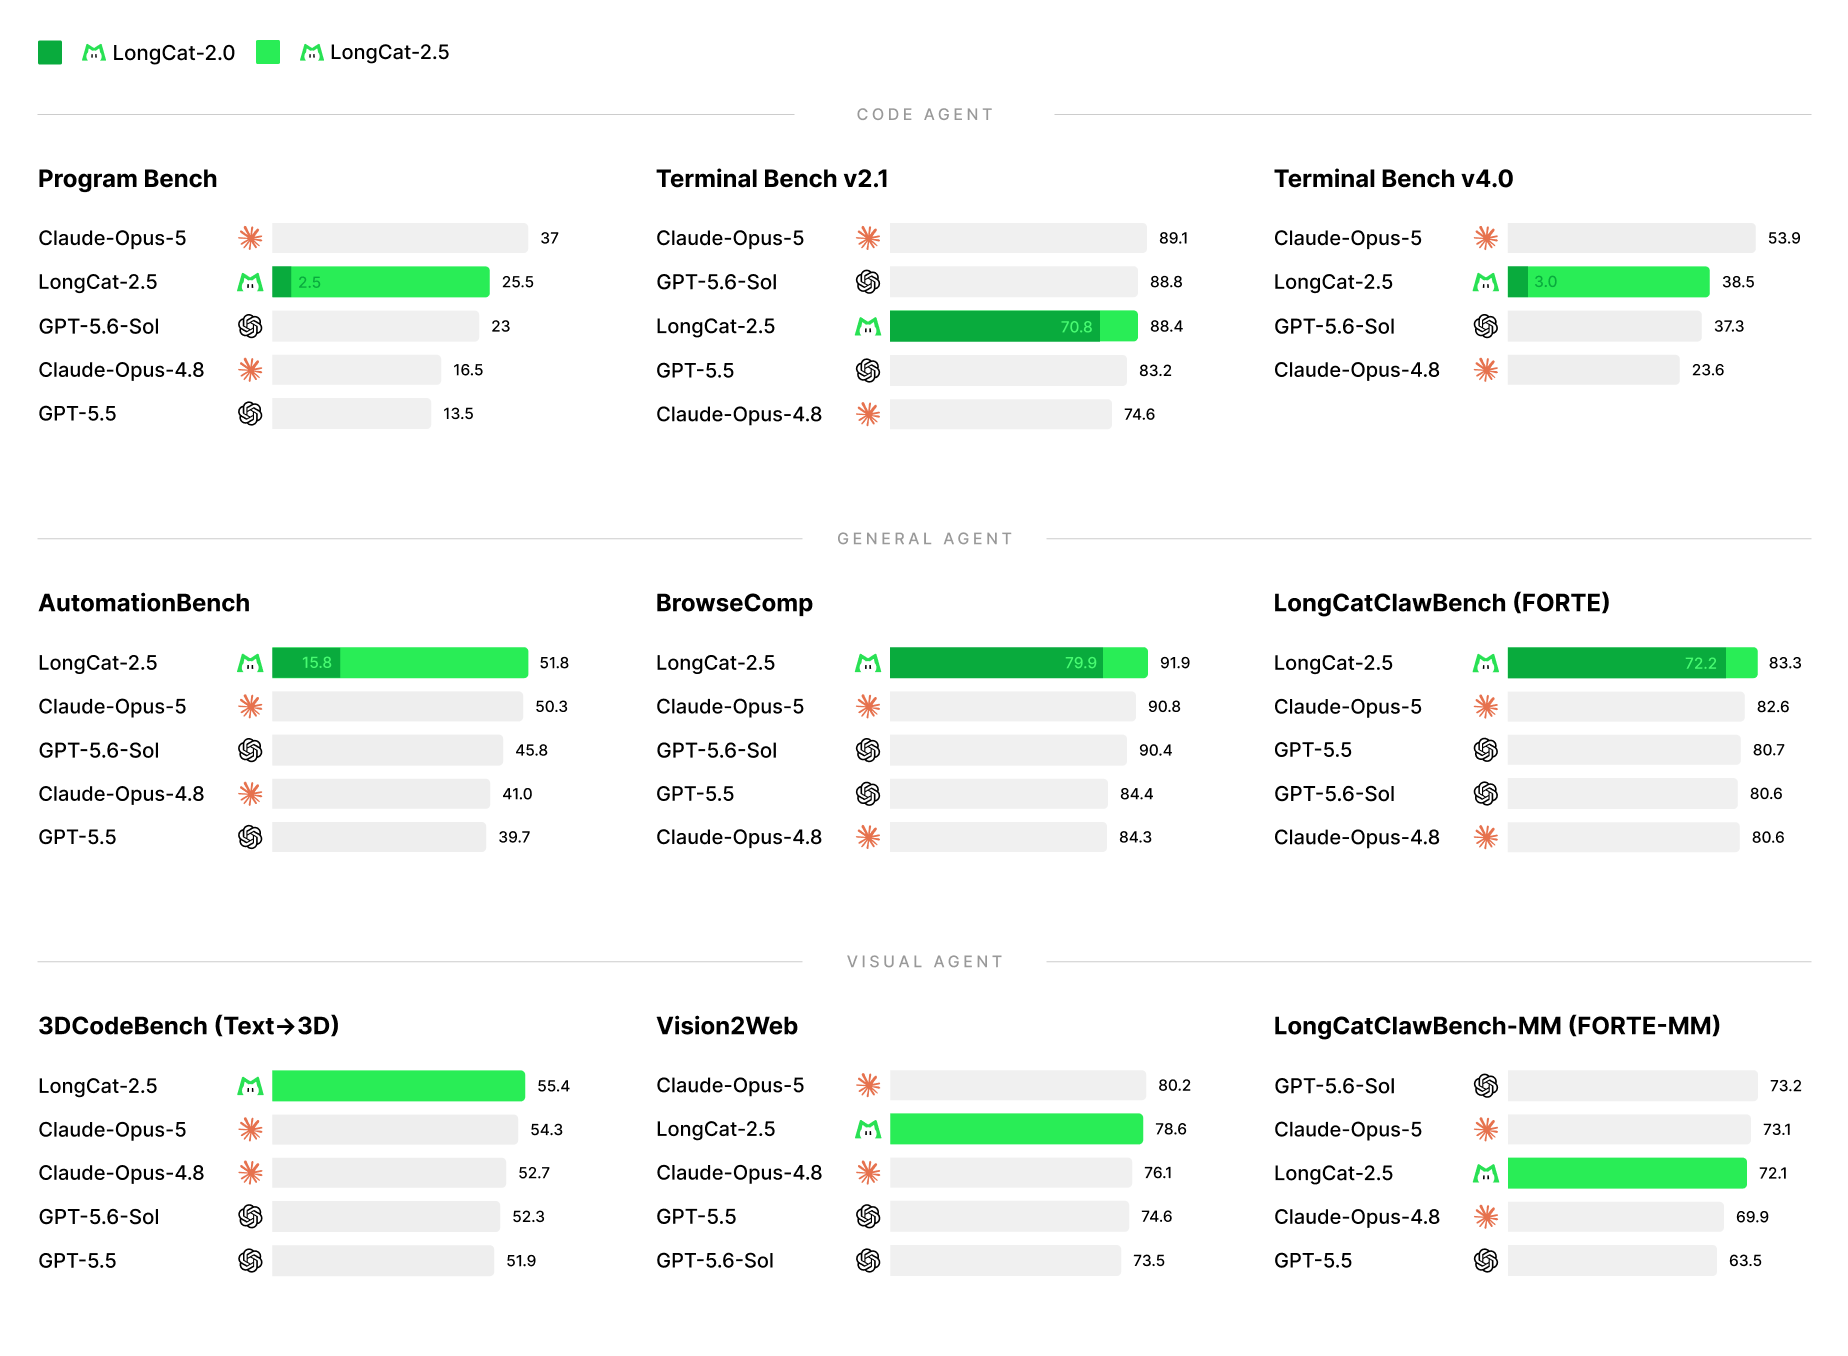
The model card carries its evaluation results as a table and a chart. The chart sets LongCat-2.5 beside Claude-Opus-5, GPT-5.6-Sol, Claude-Opus-4.8 and GPT-5.5 on nine benchmarks in three groups: code agent, general agent and visual agent. It lists 91.9 on BrowseComp and 88.4 on Terminal Bench v2.1, for example. All of these scores are the ones Meituan put on the card. The card says scores marked with an asterisk are cited from public technical reports, blog posts or official leaderboards, while unmarked scores were measured in-house and are indicative only. The LongCat-2.5 scores shown in the chart all appear without an asterisk in the table.모델 카드에는 평가 결과가 표와 차트로 실려 있습니다. 차트는 코드 에이전트, 범용 에이전트, 시각 에이전트 세 묶음에 벤치마크를 세 개씩 두고 LongCat-2.5를 Claude-Opus-5, GPT-5.6-Sol, Claude-Opus-4.8, GPT-5.5와 나란히 놓았습니다. 예를 들어 BrowseComp는 91.9, Terminal Bench v2.1은 88.4로 적혀 있습니다. 이 점수는 모두 Meituan이 모델 카드에 적은 값입니다. 카드는 별표가 붙은 점수는 공개된 기술 보고서나 블로그 글, 공식 리더보드에서 옮긴 것이고, 별표가 없는 점수는 사내에서 잰 참고용 값이라고 밝혔습니다. 차트에 나온 LongCat-2.5 점수는 표에서 모두 별표 없이 적혀 있습니다.
The weights sit in the meituan-longcat/LongCat-2.5 repository on Hugging Face. The repository is not gated, and the page data puts the safetensors files at about 3.56 TB in total. The tensor types are shown as BF16 and F32. On deployment, the card says LongCat-2.5 can be deployed on NPU platforms and refers readers to SGLang-FluentLLM for how. It also gives longcat.ai as the official website for chatting with the model.가중치는 Hugging Face의 meituan-longcat/LongCat-2.5 저장소에 있습니다. 접근 신청을 거치는 설정은 걸려 있지 않고, 페이지 정보로는 safetensors 파일을 합쳐 약 3.56TB입니다. 텐서 형식은 BF16과 F32로 표시됩니다. 배포에 관해 카드는 LongCat-2.5를 NPU 플랫폼에 올릴 수 있다고 적고, 방법은 SGLang-FluentLLM을 참고하라고 안내합니다. 대화로 써 볼 수 있는 공식 웹사이트로는 longcat.ai를 적어 두었습니다.
The license comes with a caveat. The card says the model weights are released under the MIT License and adds that the license does not grant any rights to use Meituan trademarks or patents. Under usage considerations, it says the model has not been specifically designed or comprehensively evaluated for every possible downstream application. The numbers also differ between two places: Meituan gives 1.6 trillion total parameters, while the file information on Hugging Face shows 1.8T params. Neither place explains the difference.라이선스에는 단서가 붙어 있습니다. 카드는 모델 가중치를 MIT 라이선스로 공개한다고 적으면서, 이 라이선스가 Meituan의 상표나 특허를 쓸 권리까지 주는 것은 아니라고 덧붙였습니다. 사용 시 유의 사항으로는 이 모델이 가능한 모든 쓰임새에 맞춰 설계되거나 종합적으로 평가된 것이 아니라고 적었습니다. 숫자도 두 곳이 다릅니다. Meituan은 전체 매개변수를 1.6조 개라고 밝혔는데, Hugging Face의 파일 정보에는 1.8T params로 표시됩니다. 왜 다른지는 두 곳 어디에도 설명이 없습니다.
The chart needs to be read alongside the table. It shows four other models, but the table on the same card also includes GLM-5.3, kimi-k3 and DeepSeek-V4.1-Flash. On LongCatClawBench (FORTE), where the chart puts LongCat-2.5 at the top, the table lists kimi-k3 at 86.3 and GLM-5.3 at 85.6, above LongCat-2.5 at 83.3. On Terminal Bench v2.1, DeepSeek-V4.1-Flash is the highest at 90.6. These values, too, are the ones Meituan put in the card's table. The card does not state the hardware needed to run the model.차트는 표와 같이 읽어야 합니다. 차트에는 비교 모델이 넷만 나오지만, 같은 카드의 표에는 GLM-5.3, kimi-k3, DeepSeek-V4.1-Flash도 들어 있습니다. 차트에서 LongCat-2.5가 맨 위에 놓인 LongCatClawBench (FORTE)는 표에서 kimi-k3가 86.3, GLM-5.3이 85.6으로 LongCat-2.5의 83.3보다 높습니다. Terminal Bench v2.1에서는 DeepSeek-V4.1-Flash가 90.6으로 가장 높습니다. 이 값들도 Meituan이 카드의 표에 적은 것입니다. 모델을 돌리는 데 필요한 장비 사양은 카드에 나와 있지 않습니다.
Keep reading더 읽기
All articles전체 글TencentTencent
Tencent releases Hy4 flash as open weights, with FP8 and base versions, under the Tencent Hy LicenseTencent, Hy4 flash 가중치 공개 — FP8 · base 모델 포함, Tencent Hy License
Checked확인일
Chart: Tencent Hy4 flash model card. Tencent internal testing.그림: Tencent Hy4 flash 모델 카드. Tencent 내부 시험 결과입니다.
ElevenLabsElevenLabs
ElevenLabs releases Scribe v3 Live Medical, real-time medical transcription for voice agents in ElevenAgentsElevenLabs, ElevenAgents 음성 에이전트용 실시간 의료 전사 Scribe v3 Live Medical 공개
Checked확인일
Image: ElevenLabs blog.그림: ElevenLabs 블로그.
GoogleGoogle
Google launches a Robotics plugin for Google Antigravity that sets up, simulates and controls robot arms with Gemini 4 HydrogenGoogle, Gemini 4 Hydrogen으로 로봇 팔을 준비·시뮬레이션·제어하는 Google Antigravity용 Robotics 플러그인 공개
Checked확인일
Video still: Google Developers Blog.영상 장면: Google Developers 블로그.


