 HREN


ElevenLabs launches Scribe v3 and Scribe v3 Live speech to text modelsElevenLabs, 음성 받아쓰기 모델 Scribe v3와 Scribe v3 Live 공개
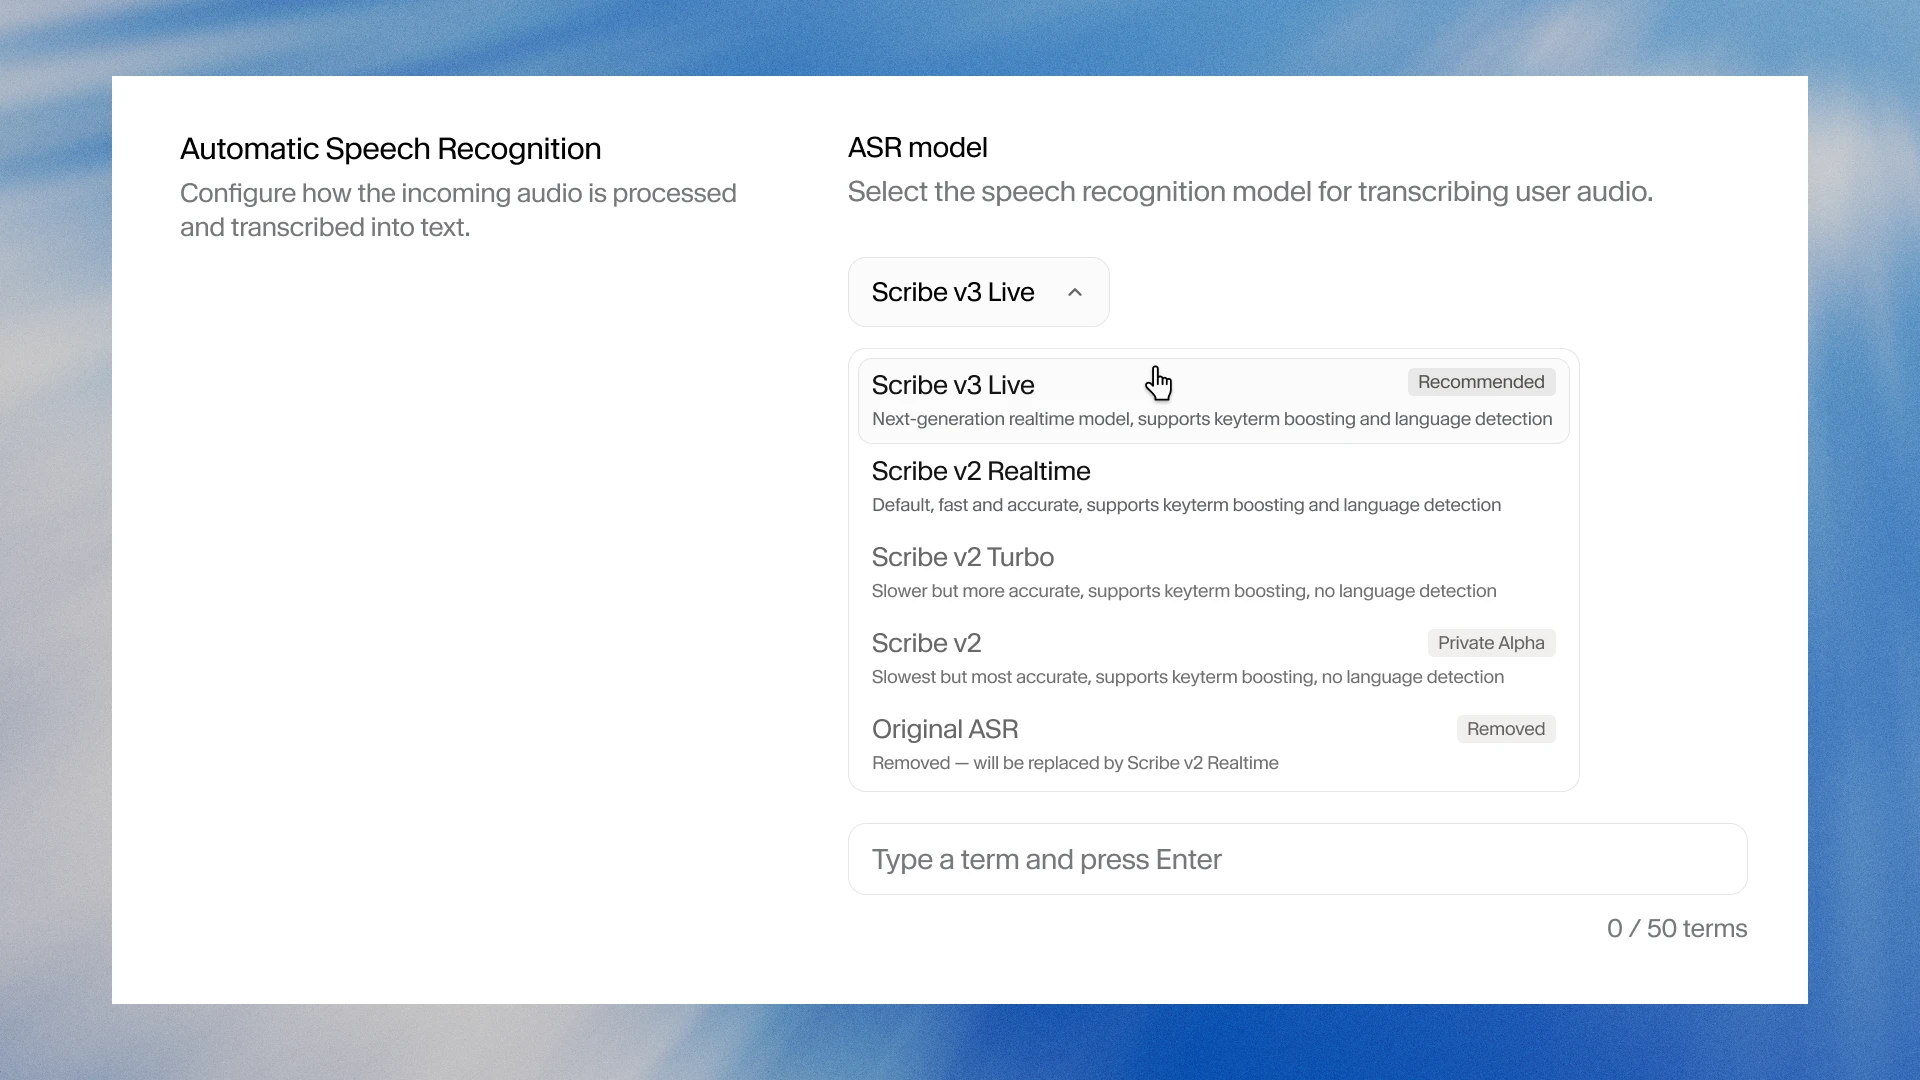
ElevenLabs has launched Scribe v3 for recorded audio and Scribe v3 Live for realtime audio. By ElevenLabs' own measurements, Scribe v3 makes 27% fewer word errors than Scribe v2 across 102 languages, and Scribe v3 Live adds speaker diarization to realtime transcription for the first time. Scribe v3 Live is available in ElevenAgents, both models are available in ElevenAPI, and both run in the US by default.ElevenLabs가 녹음된 오디오용 Scribe v3와 실시간 오디오용 Scribe v3 Live를 내놓았습니다. ElevenLabs가 직접 잰 결과로 Scribe v3는 102개 언어에서 Scribe v2보다 단어 오류가 27% 적고, Scribe v3 Live에는 말한 사람을 가르는 화자 분리가 처음 들어갔습니다. Scribe v3 Live는 ElevenAgents에서, 두 모델은 ElevenAPI에서 쓸 수 있고, 두 모델은 기본으로 미국에서 돌아갑니다.
- Source published원문 게시일
- Checked확인일
ElevenLabs has launched two new speech to text models. Scribe v3 is for recorded audio, and Scribe v3 Live is the low latency variant for realtime audio. By ElevenLabs' own measurements, Scribe v3 makes 27% fewer word errors than Scribe v2 across 102 languages, and Scribe v3 Live cuts semantic word error rate by 43% and word error rate by 31% compared with Scribe v2 Realtime. Scribe v3 Live also includes speaker diarization, labeling who said what, for the first time, along with improved turn detection.ElevenLabs가 음성을 글로 옮기는 새 모델 둘을 내놓았습니다. Scribe v3는 녹음된 오디오용이고, Scribe v3 Live는 실시간 오디오를 위한 지연이 짧은 판입니다. ElevenLabs가 직접 잰 결과로는 Scribe v3가 102개 언어에서 Scribe v2보다 단어 오류가 27% 적고, Scribe v3 Live는 Scribe v2 Realtime보다 의미가 바뀌는 오류(semantic WER)가 43%, 단어 오류가 31% 적습니다. Scribe v3 Live에는 누가 어떤 말을 했는지 가르는 화자 분리(diarization)가 처음 들어갔고, 말이 끝났는지 알아채는 기능도 나아졌습니다.
ElevenLabs says Scribe v3 makes 17% fewer diarization errors than Scribe v2 on recordings with three or more speakers. Turn detection in Scribe v3 Live uses the context of the conversation as well as the audio rather than silence alone, so a caller who pauses halfway through a number is not cut off; it is the same turn detection ElevenAgents already uses, now available in ElevenAPI. Scribe v3 can infer which languages a recording may contain and lets users choose whether numbers come back as digits or words. Keyterm prompting accepts terms that are known to come up, such as brand names, acronyms and jargon, and transcript edits apply formatting rules written in plain English, such as “write every date as YYYY-MM-DD.” Scribe v3 Live adds a multilingual mode for conversations that switch languages mid-sentence and a keyterm library that holds thousands of terms and is consulted only when the model hears a likely match.ElevenLabs는 세 명 이상이 말하는 녹음에서 Scribe v3의 화자 분리 오류가 Scribe v2보다 17% 적다고 밝혔습니다. Scribe v3 Live의 말 차례 판단은 말이 멈춘 시간만 보지 않고 대화 맥락과 소리를 함께 보고, 숫자를 읽다 중간에 멈춘 사람의 말을 끊지 않게 했습니다. ElevenAgents가 이미 쓰던 이 방식을 이제 ElevenAPI에서도 쓸 수 있습니다. Scribe v3는 녹음에 어떤 언어가 들었을지 알아내고, 숫자를 숫자로 낼지 글자로 낼지 고르게 하며, 상표 이름, 약어, 전문 용어처럼 나올 줄 아는 단어를 미리 주는 keyterm prompting과 “write every date as YYYY-MM-DD” 같은 평이한 영어 규칙으로 서식을 맞추는 transcript edits를 갖췄습니다. Scribe v3 Live는 문장 중간에 언어가 바뀌는 대화를 위한 다국어 모드와, 수천 개의 용어를 넣어 두고 비슷한 말이 들릴 때만 찾아보는 keyterm library를 더했습니다.
Scribe v3 Live is available in ElevenAgents from launch day, and both models are available in ElevenAPI. Existing integrations upgrade from Scribe v2 by changing the model ID to scribe_v3 or scribe_v3_live. A version of Scribe v3 Live optimized for medical conversations is also being released in ElevenAgents for healthcare teams. Eneco, which supplies energy to more than 2 million homes and businesses in the Netherlands, tested Scribe v3 Live on its ElevenAgents voice agent ahead of launch, and ElevenLabs reports that in Eneco's real customer calls the agent recognized Dutch postcodes correctly on the first try 40% more often, and house numbers 15% more often.Scribe v3 Live는 발표 날부터 ElevenAgents에서 쓸 수 있고, 두 모델 모두 ElevenAPI에도 열렸습니다. 이미 Scribe v2로 연동한 곳은 모델 ID를 scribe_v3나 scribe_v3_live로 바꾸면 됩니다. 의료 팀을 위해 의료 대화에 맞춘 Scribe v3 Live 판도 ElevenAgents에 함께 나왔습니다. 네덜란드에서 200만 곳이 넘는 가정과 사업장에 에너지를 공급하는 Eneco는 출시 전에 ElevenAgents로 돌리는 음성 에이전트에서 Scribe v3 Live를 시험했고, ElevenLabs가 전한 Eneco의 실제 고객 통화 결과로는 네덜란드 우편번호를 첫 시도에 맞게 알아들은 경우가 40%, 집 번호는 15% 늘었습니다.
Both models run in the US by default, and isolated environments in the EU, India and Singapore are offered to enterprise customers with data residency requirements. Zero Retention Mode deletes audio and text as soon as a request completes. Both models are covered by ElevenLabs' SOC 2, ISO 27001 and PCI DSS Level 1 programs, are HIPAA-eligible with a Business Associate Agreement, and are available for private deployment. The error rate and diarization figures were measured by ElevenLabs on an internal version of the FLEURS benchmark and on its own dataset of real meetings, agent calls and voice notes across 16 languages, which it says it will open source soon. Each language was scored on its own before averaging, so the results are not directly comparable with figures measured in other ways, and ElevenLabs notes that its realtime diarization results cannot be compared with its batch diarization results.두 모델은 기본으로 미국에서 돌아가고, 데이터 보관 위치 요건이 있는 기업 고객에게는 EU, 인도, 싱가포르의 분리된 환경이 따로 제공됩니다. Zero Retention Mode에서는 요청이 끝나면 바로 오디오와 글을 지웁니다. 두 모델은 ElevenLabs의 SOC 2, ISO 27001, PCI DSS Level 1 프로그램 범위에 들고, Business Associate Agreement가 있으면 HIPAA 대상 업무에 쓸 수 있으며, 비공개 배포도 됩니다. 오류 수치와 화자 분리 수치는 ElevenLabs가 FLEURS 벤치마크의 내부판과, 16개 언어의 실제 회의, 에이전트 통화, 음성 메모로 만든 자체 데이터로 잰 것이고, 이 자체 데이터는 곧 공개할 예정이라고 밝혔습니다. 언어마다 따로 점수를 낸 뒤 평균한 방식이라 다른 방식으로 잰 결과와는 바로 견줄 수 없고, 실시간 화자 분리 수치도 녹음용 화자 분리 수치와는 비교할 수 없다고 ElevenLabs는 적었습니다.
Keep reading더 읽기
All articles전체 글TencentTencent
Tencent releases Hy4 flash as open weights, with FP8 and base versions, under the Tencent Hy LicenseTencent, Hy4 flash 가중치 공개 — FP8 · base 모델 포함, Tencent Hy License
Checked확인일
Chart: Tencent Hy4 flash model card. Tencent internal testing.그림: Tencent Hy4 flash 모델 카드. Tencent 내부 시험 결과입니다.
ElevenLabsElevenLabs
ElevenLabs releases Scribe v3 Live Medical, real-time medical transcription for voice agents in ElevenAgentsElevenLabs, ElevenAgents 음성 에이전트용 실시간 의료 전사 Scribe v3 Live Medical 공개
Checked확인일
Image: ElevenLabs blog.그림: ElevenLabs 블로그.
GoogleGoogle
Google launches a Robotics plugin for Google Antigravity that sets up, simulates and controls robot arms with Gemini 4 HydrogenGoogle, Gemini 4 Hydrogen으로 로봇 팔을 준비·시뮬레이션·제어하는 Google Antigravity용 Robotics 플러그인 공개
Checked확인일
Video still: Google Developers Blog.영상 장면: Google Developers 블로그.


