HREN


GTA world model, Apache-2.0 open weights and a streaming server that turn one start image and held keys into video frame by frame on a CUDA GPUGTA world model, 시작 그림 한 장과 누른 키로 영상을 틀마다 이어 만드는 Apache-2.0 공개 가중치와 CUDA GPU 서버
GTA world model is the weights and inference code of an interactive world model that takes one start image and generates the video that follows from the keys a user holds, one frame at a time, streaming it to a browser; it is in the Hugging Face repository lucidml/gta under Apache License 2.0. It runs on CUDA GPUs only, the server listens on 0.0.0.0:3002 and one GPU process serves one player at a time, and neither the browser client nor training code is in the repository. The README says this checkpoint was trained from scratch on GG800, an 800-hour GTA5 dataset.GTA world model은 시작 그림 한 장을 받고 사용자가 누르고 있는 키에 맞춰 이어지는 영상을 한 틀씩 만들어 브라우저로 보내는 대화형 세계 모델의 가중치와 추론 코드로, Hugging Face 저장소 lucidml/gta에 Apache License 2.0으로 있습니다. CUDA GPU에서만 돌고, 서버는 0.0.0.0:3002에서 열리며 GPU 프로세스 하나가 한 번에 한 사람만 받고, 브라우저 쪽 프로그램과 학습 코드는 저장소에 없습니다. README는 이 체크포인트를 800시간 분량의 GTA5 데이터셋 GG800으로 처음부터 학습했다고 적습니다.
- Checked확인일
GTA world model is an interactive world model that takes one start image and then generates the video that follows from the keys a user holds, one frame at a time, streaming it to a browser. The Hugging Face repository lucidml/gta holds its weights and the complete inference runtime (the model, its memory, the sampler and the streaming server) under Apache License 2.0, so redistributors must pass on a copy of the license and there is no warranty, and there is no training code in the repository. The README says this checkpoint was trained from scratch on GG800, an 800-hour GTA5 dataset.GTA world model은 시작 그림 한 장을 받은 뒤 사용자가 누르고 있는 키에 맞춰 이어지는 영상을 한 틀씩 만들어 브라우저로 흘려보내는 대화형 세계 모델이고, Hugging Face 저장소 lucidml/gta에 가중치와 추론 실행 코드(모델, 메모리, 샘플러, 스트리밍 서버)가 Apache License 2.0으로 올라와 있습니다. 다시 나누는 쪽은 라이선스 사본을 함께 줘야 하고 보증은 없으며, 학습 코드는 저장소에 없습니다. README는 이 체크포인트를 800시간 분량의 GTA5 데이터셋 GG800으로 처음부터 학습했다고 적습니다.
It needs a CUDA GPU, and the README says it is CUDA only; Python needs torch (with FlexAttention and torch.compile), numpy, fastapi, uvicorn, pillow, av and imageio, with flash_attn optional. Everything the server needs is in the repository at the paths set in the CONFIG dict at the top of summary_server.py: the model checkpoint serve_ckpts/gta_model.pt, the autoencoder sae_compact.pt and the two latent-statistics files latent_stats_z0.pt and latent_stats_z_rest.pt. The server runs on the machine where the repository is downloaded and started, listening on 0.0.0.0:3002 (every network address); the start image is uploaded to that server through POST /z0/{user_id}, and the session and generated video pass over that server’s WS /ws/{user_id} WebSocket. Supported operating systems, authentication for connecting to the server, connection encryption and cost are not stated in the README. At startup it loads the weights, compiles the model and plays a short warm-up session, so the first start takes a while, one GPU process serves one player at a time, and the memory window is 24 frames in training but 16 by the server default. The browser client is not in the repository and has to be provided separately against the protocol in the README, and a session stops when it uses up 4,096 frame ids or reaches the per-session wall-clock limit (ws_session_limit_s, 180 s by default, 0 disables it).돌리려면 CUDA GPU가 있어야 하고(README는 CUDA만 된다고 적습니다), Python에 torch(FlexAttention과 torch.compile), numpy, fastapi, uvicorn, pillow, av, imageio가 필요하며 flash_attn은 골라 씁니다. 서버에 필요한 파일은 모두 저장소 안, summary_server.py 맨 위 CONFIG 사전이 가리키는 자리에 있으며, 모델 체크포인트 serve_ckpts/gta_model.pt, 오토인코더 sae_compact.pt, 잠재 통계 파일 latent_stats_z0.pt와 latent_stats_z_rest.pt가 그것입니다. 서버는 저장소를 받아 켠 컴퓨터에서 돌고 0.0.0.0:3002(모든 네트워크 주소)에서 열리며, 시작 그림은 POST /z0/{user_id}로 그 서버에 올라가고 세션과 만든 영상은 그 서버의 WS /ws/{user_id} 웹소켓으로 오갑니다. 지원 운영체제, 서버 접속 인증, 연결 암호화, 비용은 README에 나와 있지 않습니다. 처음 켤 때 가중치를 읽고 모델을 컴파일한 뒤 짧은 예열 세션을 돌려 시간이 걸리고, GPU 프로세스 하나가 한 번에 한 사람만 받으며, 메모리 창은 학습 때 24틀이지만 서버는 기본 설정으로 16틀을 씁니다. 브라우저 쪽 프로그램은 저장소에 없어 README의 프로토콜에 맞춘 것을 따로 갖춰야 하고, 세션은 틀 번호 4096개를 다 쓰거나 세션마다 걸린 시간 상한(ws_session_limit_s, 기본 180초, 0이면 꺼짐)에 닿으면 멈춥니다.
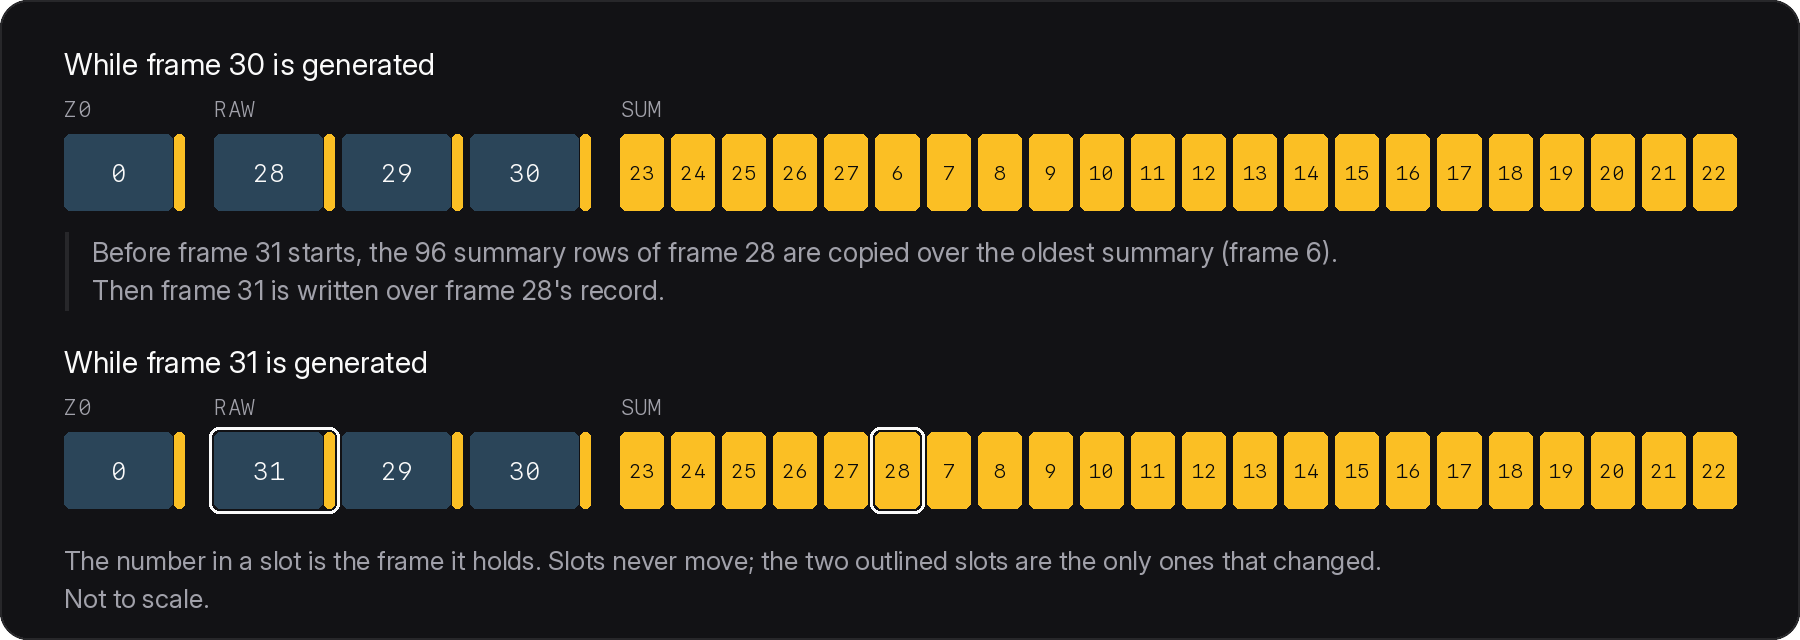
It runs by downloading the repository with hf download lucidml/gta --local-dir gta and starting python summary_server.py from its root, with settings in the CONFIG dict at the top of summary_server.py. The client sends JSON with the keys currently held (w, a, s, d, shift, space, left, right), and the server sends back binary messages of one byte marking a key frame (0x01) or a delta frame (0x00) followed by an H.264 Annex-B access unit at 384x672. The architecture is called Summaryformer: with the trained 24-frame window, the start image and the newest 3 frames are kept whole, and 22 older frames are kept as 96 summary tokens each (the server default window is 16 frames).실행은 hf download lucidml/gta --local-dir gta로 저장소를 받은 뒤 그 뿌리에서 python summary_server.py를 돌리는 방식이고, 설정은 summary_server.py 맨 위 CONFIG 사전에 있습니다. 클라이언트는 지금 누르고 있는 키(w, a, s, d, shift, space, left, right)를 JSON으로 보내고, 서버는 키 프레임(0x01)인지 차이 프레임(0x00)인지 알리는 한 바이트 뒤에 384x672 크기의 H.264 Annex-B 단위를 붙인 이진 메시지로 영상을 돌려보냅니다. 구조 이름은 Summaryformer로, 학습한 24틀 창에서는 시작 그림과 가장 최근 3틀은 통째로 두고 그보다 오래된 22틀은 틀마다 요약 토큰 96개로만 남겨 기억합니다(서버 기본 창은 16틀).
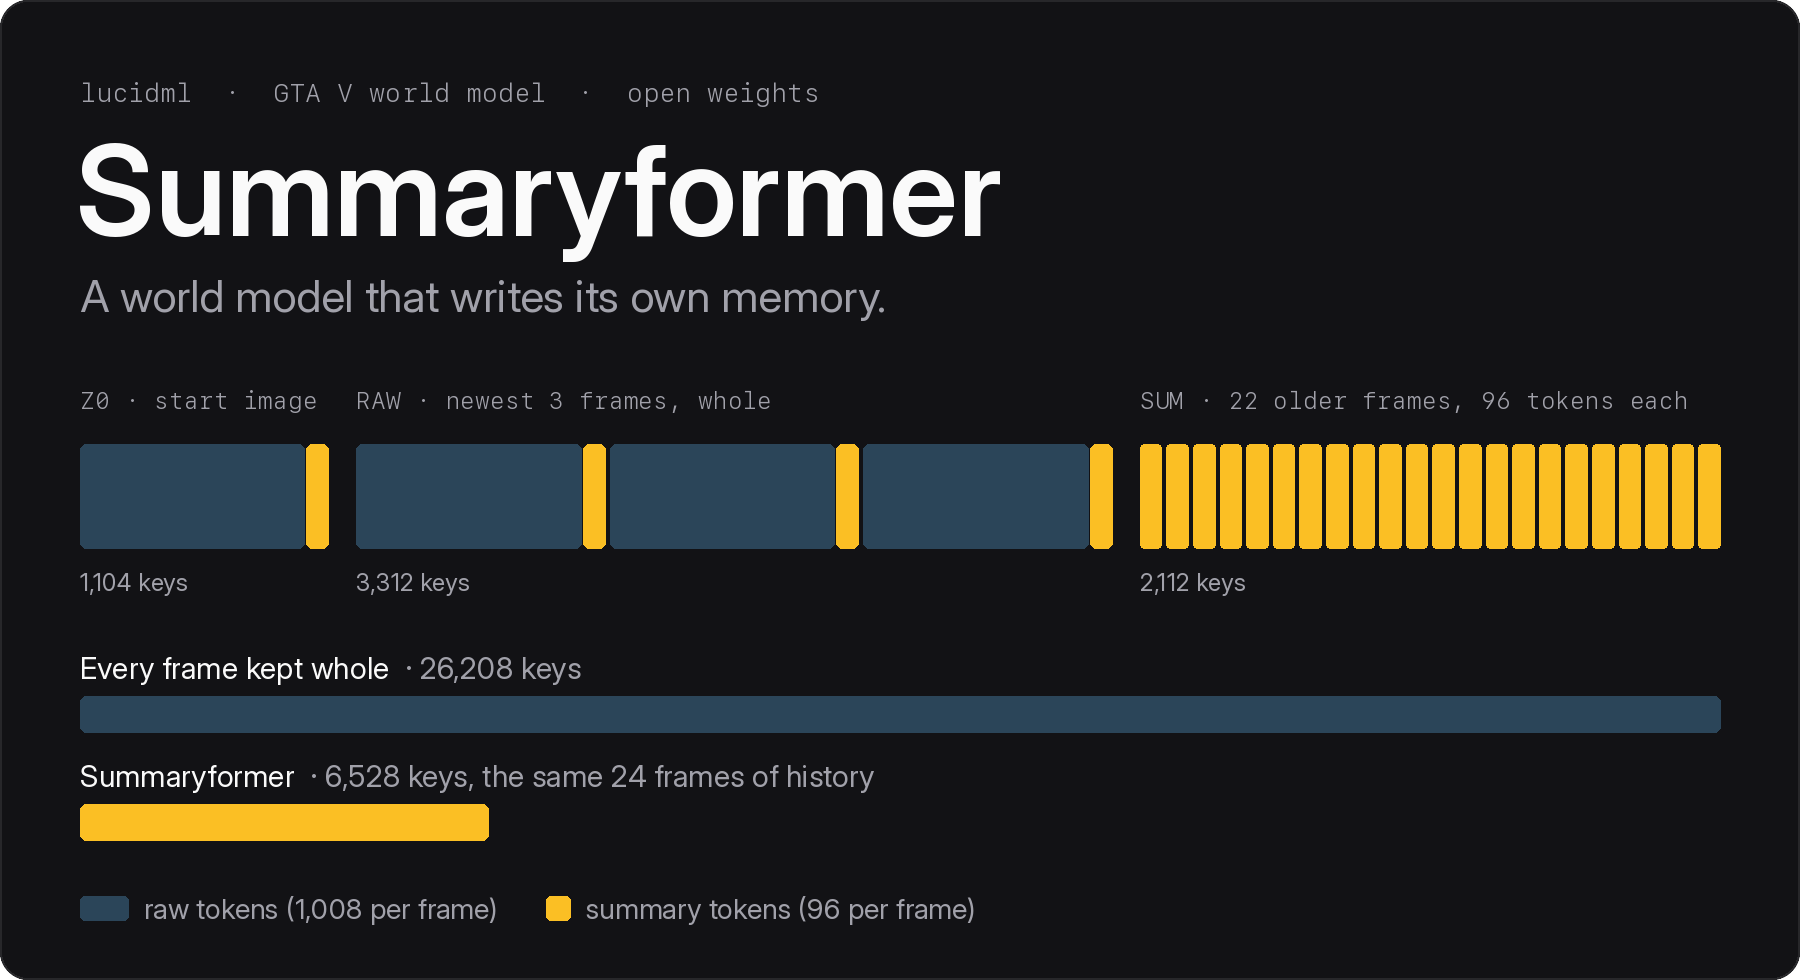
By the README’s figures the model has 630,205,008 parameters, and at the served resolution with the trained 24-frame window (not the server default of 16) the buffer holds 6,528 keys, against 26,208 if every frame in the same span were kept at full resolution.README가 적은 값으로 모델 매개변수는 630,205,008개이고, 서비스 해상도와 학습한 창(24틀, 서버 기본 설정의 16틀이 아님)에서 버퍼의 키는 6,528개이며 같은 구간의 모든 틀을 원래 해상도로 두면 26,208개가 됩니다.
The repository is public, and the Hugging Face model information shows it is not gated; it was created on 2026-11-10 and last modified on 2026-11-14.저장소는 공개되어 있고 Hugging Face 모델 정보에서 접근 제한(gated)은 걸려 있지 않으며, 2026-11-10에 만들어져 2026-11-14에 마지막으로 바뀌었습니다.
Sessions are finite: at startup the server extends the position table to 4,096 frame ids, and a session stops when it reaches the last one. The README’s Credits section says the KV-cached inference approach was learned from Self-Forcing and the rotary position code was adapted from Wan2.1 (Apache-2.0).세션 길이에는 끝이 있어, 서버는 시작할 때 위치 표를 틀 번호 4096개까지 늘려 두고 세션이 마지막 번호에 닿으면 멈춥니다. README의 Credits 절은 KV 캐시 추론 방식을 Self-Forcing에서 배웠고 회전 위치 코드를 Wan2.1(Apache-2.0)에서 가져와 고쳤다고 따로 밝힙니다.
Sources & references원문과 참고 자료
Keep reading더 읽기
All articles전체 글rust-anythingrust-anything
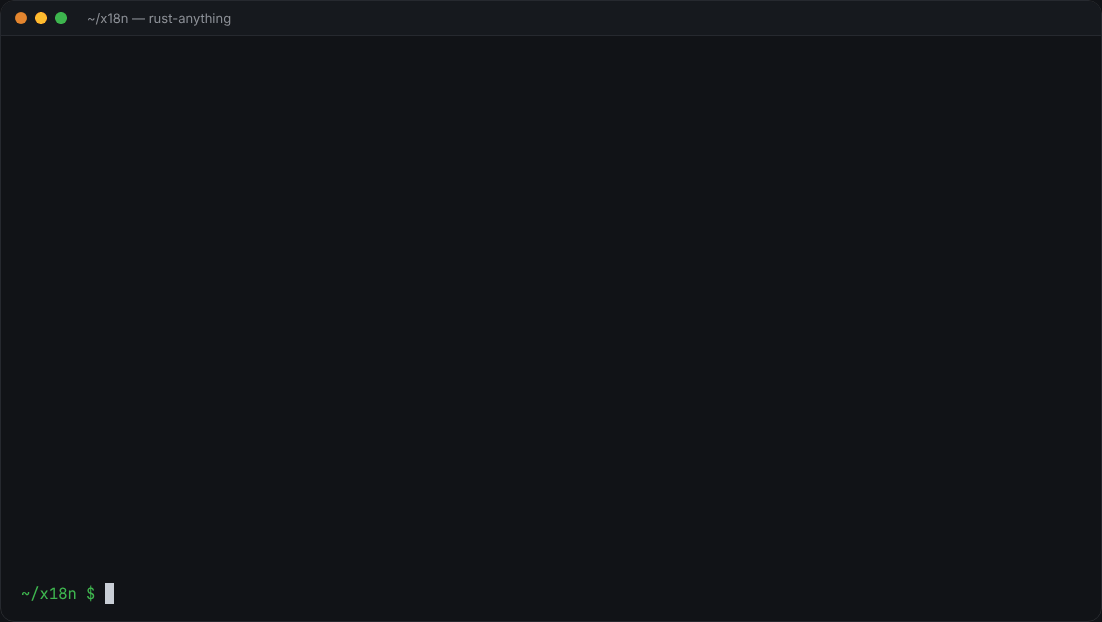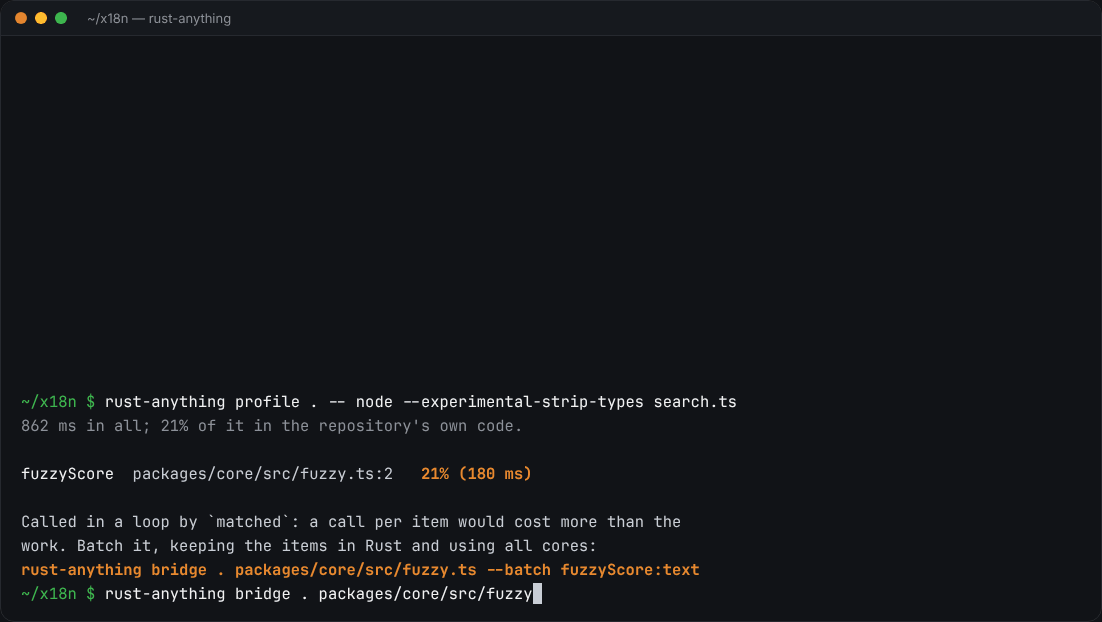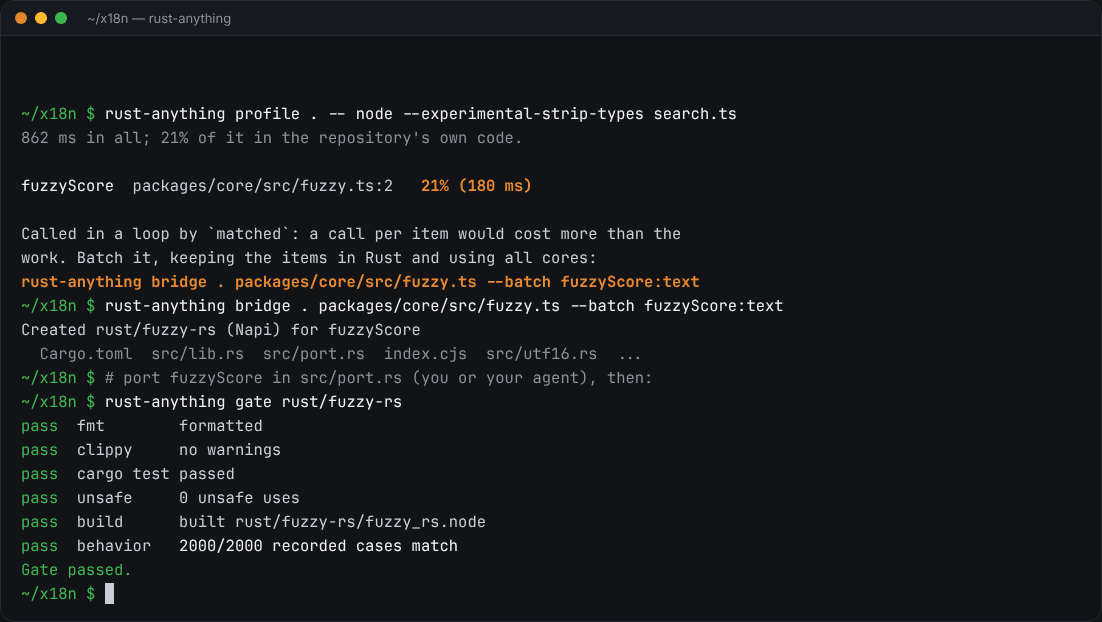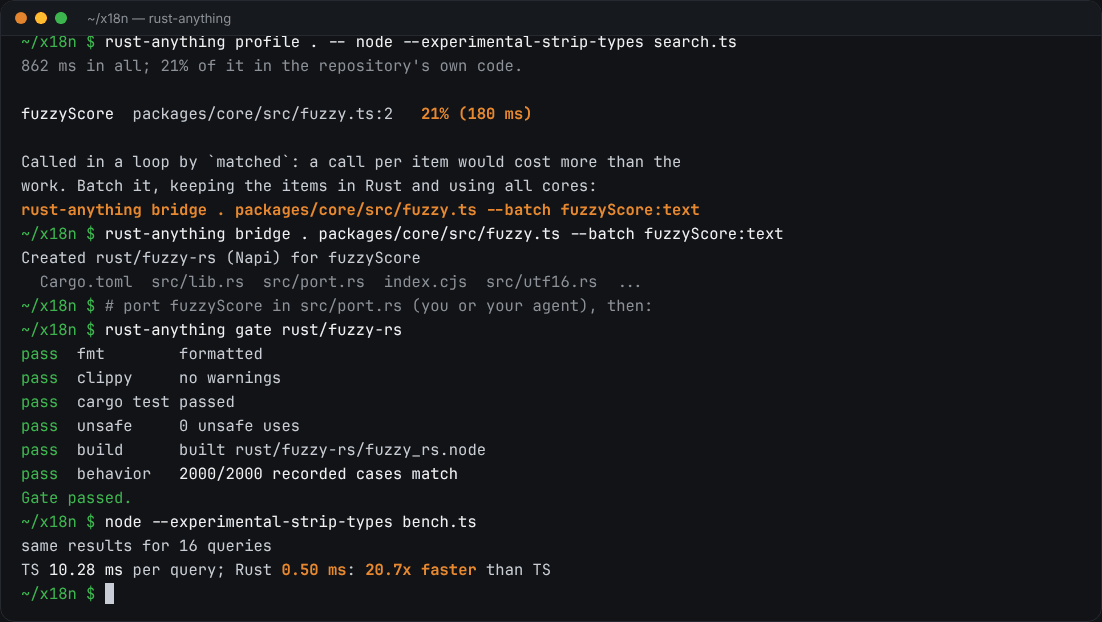
rust-anything, an MIT-licensed command-line tool that moves a Node.js, Python, C, Go, Ruby or Java app to Rust one piece at a time and checks each piece against recordings of the originalrust-anything, Node.js·Python·C·Go·Ruby·Java 앱을 한 조각씩 Rust로 옮기며 조각마다 원래 코드의 기록과 맞춰 보는 MIT License 명령줄 도구
Checked확인일
Image: rust-anything README.그림: rust-anything README.
sketchsketch
sketch, an MIT-licensed Claude Code plugin that answers with diagrams, roadmaps, wireframes and chart cards in the terminal instead of paragraphssketch, Claude Code의 답을 문단 대신 터미널 안 구조도와 로드맵, 화면 틀, 차트 카드로 그려 주는 MIT 플러그인
Checked확인일
Image: sketch README.그림: sketch README.
SketchCraftSketchCraft
SketchCraft, a free MIT-licensed 3D modeler for houses, rooms and furniture that AI agents can also drive over MCP, limited to a workspace folderSketchCraft, 윤곽을 그려 끌어올리는 무료 MIT 3D 모델러, AI 에이전트도 작업 폴더 안에서 MCP로 같은 모델을 고친다
Checked확인일
Image: SketchCraft README.그림: SketchCraft README.